Introduction
What you'll learn: a practical, vendor-neutral playbook for building and operating multitenant observability in enterprise SaaS in August 2026. This update reflects current operational patterns, cost-control practices, and regulatory considerations that engineering, platform and SRE teams must address today.
Who this is for: platform engineers, SREs, observability product managers and technical leaders responsible for telemetry, billing integration, or offering observability as a product to customers.
Why this matters now: since mid‑2025 the economics of telemetry have continued to pressure SaaS businesses. Adoption of OpenTelemetry is nearly universal, cloud providers and third‑party vendors have added tenant-aware features, and regulators and enterprise customers expect stronger data residency, access controls and encryption. Your observability design must balance scale, cost predictability, isolation and the ability to monetize monitoring without exposing you to compliance or noisy‑neighbor risk.
Prerequisites & Context
Before you start: ensure these capabilities exist or are in planning:
- Identity and provisioning: SAML/OIDC with SCIM for tenant user provisioning and RBAC mapping.
- Billing pipeline that can ingest per-tenant usage records (events, metrics, logs) or support webhooks for usage data.
- Telemetry standardization: OpenTelemetry (OTel) adoption or a transition plan if you currently use vendor SDKs.
- Cloud object storage and lifecycle policies (e.g., S3/GCS/Azure Blob) for cost-effective archive tiers.
- Security baseline: encryption in transit, key management (KMS), and an audit logging system.
Why multitenant observability still matters in 2026
Key changes since July 2026 and why they matter:
- Operational costs remain the primary driver. Teams have adopted "Observability FinOps": a cross-functional practice focused on per-tenant cost attribution, retention tiering and sampling policies to avoid runaway spend.
- Data residency and tenant isolation expectations have hardened. Large customers increasingly demand tenant‑specific data residency and per‑tenant encryption keys for evidence in audits.
- Observability is productized more widely: vendors and platform teams expose tiered monitoring as a paid feature (retention tiers, higher trace sampling, advanced analytics), so correct chargeback and usage metering are critical.
- Telemetry sources have diversified: eBPF and kernel-level telemetry for network and security observability are now common in production fleets, increasing both value and cardinality risk.
- AI/ML-enhanced anomaly detection is standard in commercial products; however, it raises new privacy and explainability requirements when applied to cross-tenant datasets.
Core design choices: shared, isolated or hybrid (revisited)
The shared vs isolated decision remains fundamental. The common 2026 pattern is hybrid by default.
Shared (logical multi-tenancy — updated)
- Architecture: single ingestion and storage layer with tenant identifiers in metadata and strict RBAC at query time.
- When to choose: high tenant counts with low per-tenant telemetry volume, or when cross-tenant analytics are valuable (e.g., global product metrics).
- New 2026 considerations: support for tenant-scoped encryption keys (KMS scoped per-tenant) and policy engines to enforce retention differences without physical separation.
Isolated (per-tenant or per-customer clusters — updated)
- Architecture: dedicated storage/compute per large customer or regulated tenant; often implemented as separate cloud accounts or clusters.
- When to choose: customers with strict compliance, residency, or contractual isolation requirements; also the simplest path to per‑tenant SLO guarantees.
- New 2026 considerations: cloud providers now offer "confidential compute" and isolated enclave patterns that let you provide isolation without a full cluster per tenant for some workloads.
Hybrid—most common in 2026
Default strategy: logical multi-tenancy for small/medium tenants; dedicated ingestion or compute slices (shards, namespaces, or dedicated clusters) for large or regulated tenants. This balances cost and contractual obligations while enabling upsells.
Architecture blueprint: updated components and integration points
Core layers and modern choices you should plan for:
- Instrumentation: Continue standardizing on OpenTelemetry (OTLP). Add eBPF-based collectors for host/network observability where needed. Always propagate a validated tenant_id and correlate it across traces, logs and metrics.
- Edge / Collector: Use a mix of sidecars, node agents and centralized collectors. In 2026, serverless collectors (managed collector pools) and vectorized binary collectors reduce operational burden. Enforce tenant-aware sampling, PII scrubbing and rate limiting at this layer.
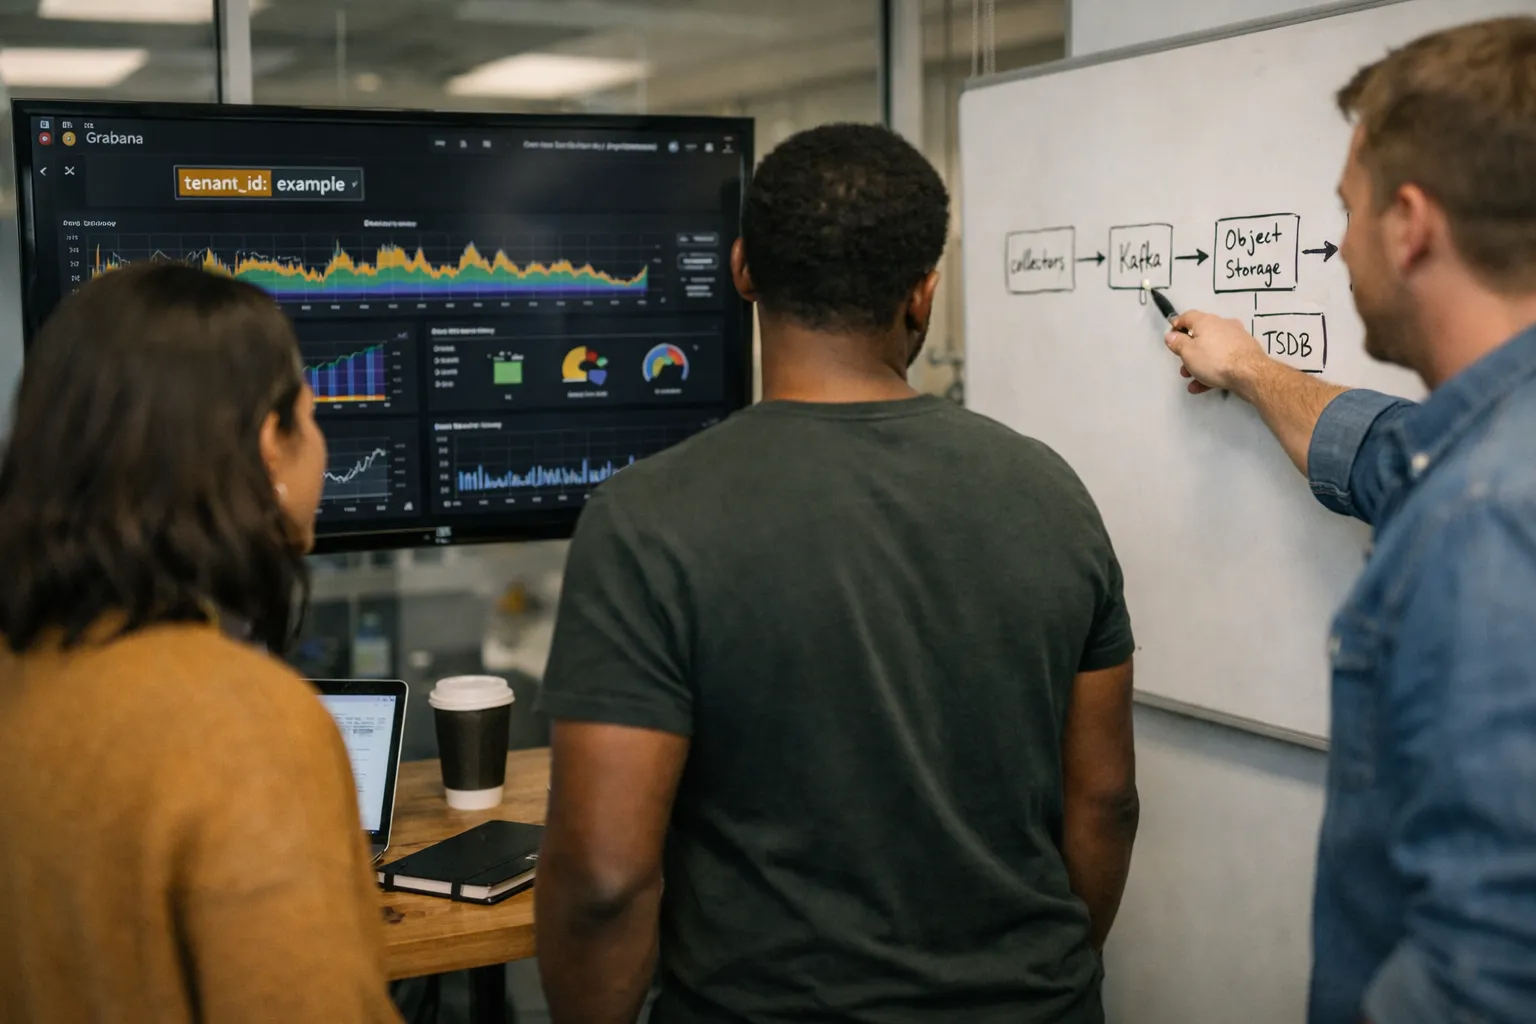
- Ingestion bus: Keyed partitioning via Kafka or cloud-managed streaming (Kinesis, Pub/Sub) remains best practice for ordering and backpressure handling. Consider tiered ingest paths: high‑value telemetry to hot pipelines, low‑value to cold/archival pipelines.
- Storage & index: Time-series backends (e.g., Cortex/Thanos patterns), trace stores, and log indexers. Store tenant identifiers as first-class partitioning keys and use object storage with Parquet/ORC for long-term archives and cost-effective analytics.
- Query & visualization: Enforce tenant scoping at the gateway/API layer with per-tenant query quotas and time limits. Grafana, custom UIs or vendor UIs are common—cache common dashboards and precompute SLIs.
- Integrations: Billing, SIEM, ticketing and identity. Provide data-export APIs so tenants can pull their telemetry for audits.
Step-by-step implementation (numbered)
Follow this phased plan to minimize disruption and create measurable wins.
-
Define tenant identity, schema and SLAs
Action: publish a tenant_id schema (format, validation rules) and required metadata (region, tier, contract ID). Map tenant tiers to retention, sampling, and query SLAs.
Why: a single source of truth avoids cross‑tenant leakage and supports billing and compliance audits.
-
Standardize instrumentation
Action: adopt OpenTelemetry for traces, metrics and logs. Add mandatory middleware to propagate tenant_id across services and at the API gateway. Provide SDK wrappers or templates for common languages to reduce errors.
Why: consistent telemetry with tenant context eliminates ambiguity during incident response and supports per-tenant cost attribution.
-
Deploy collector layer with tenant-aware policies
Action: roll out collectors that perform enrichment, PII scrubbing, sampling and tenant-aware rate limiting. Implement early rejection of malformed tenant IDs.
Why: reducing cardinality and filtering noisy or debug-level logs at the edge saves storage and prevents noisy neighbor effects.
-
Build an ingestion and partitioning strategy
Action: route telemetry into hot/cold paths. Key streams by tenant_id for ordering and shard storage by tenant hash ranges. Use separate topics/streams for high-cardinality data.
Why: predictable throughput and easier shard rebalancing at scale.
-
Implement storage tiering and lifecycle policies
Action: define retention tiers (e.g., 7/30/365) and move cold data to compressed object storage in columnar formats weekly. Expose retention as a paid tier.
Why: most telemetry value is recent; tiering delivers major cost savings and creates productized upsell opportunities.
-
Enforce query controls and precomputation
Action: set per-tenant concurrent query limits, max result sizes, and run preaggregate jobs (hourly/daily) for common SLIs. Cache dashboards with TTLs.
Why: prevents expensive ad hoc queries from affecting shared infrastructure and ensures predictable query SLOs.
-
Integrate billing, identity and security
Action: export per-tenant usage (ingest GB, query seconds, retained bytes) to billing. Map tenant users via SCIM and enforce RBAC in the query gateway. Forward security events to SIEMs with tenant metadata.
Why: accurate chargeback and audit trails are essential for monetization and compliance.
-
Instrument the observability system itself
Action: collect telemetry for the pipeline (ingest rates, latencies, backlogs) per-tenant and alert on anomalies such as sudden cardinality jumps.
Why: you cannot manage what you cannot measure—observability for observability prevents surprises.
-
Pilot and migrate in waves
Action: pilot with internal tenants and 10–20 external customers. Run dual ingestion for critical tenants during migration. Migrate by tenant tier and region; provide migration tooling and windows for large customers.
Why: phased migration reduces risk and provides measurable validation points for KPIs.
Scalability patterns and cardinality control
Practical techniques to control cost and performance:
- Limit high-cardinality labels and use relabeling to drop or hash free-form identifiers (IDs, UUIDs) that provide little analytical value.
- Use adaptive sampling: increase trace sampling rates for paid tiers and for detected anomalies; keep baseline sampling low for free/low-tier customers.
- Shard storage by tenant hash or by customer size; for very large tenants consider dedicated shards or cluster slices.
- Preaggregate and materialize common SLI/SLAs so dashboards read from compact stores rather than raw data.
- Use batch compression and columnar storage for archived telemetry; query engines (Trino/Presto or vendor equivalents) make archived analysis cost-effective.
Security, privacy and compliance (updated)
Key practices to address heightened 2026 expectations:
- Encrypt telemetry in transit and at rest. Offer tenant-scoped KMS keys where required by contract or regulation.
- Support regional data residency by routing tenant data into region-specific storage. Offer per-tenant data export and deletion workflows to support audits and data subject requests.
- Use confidentiality features (confidential compute/enclaves) for very sensitive telemetry processing if customers require proof that plaintext telemetry is not available to platform operators.
- Log and audit access to telemetry with tenant-context and keep tamper-evident logs for compliance reviews.
Measuring ROI — practical examples
ROI for multitenant observability has operational and revenue components. Track these KPIs:
- MTTD/MTTR improvements: measure mean time to detect and mean time to recover per tenant and compute delta after changes.
- Per-tenant observability revenue: count customers upgraded to paid monitoring tiers and incremental ARR.
- Operational cost per tenant: total monthly telemetry cost (ingest + storage + query) divided by active tenants or by tenant cohort.
- Churn reduction attributable to observability: track churn rates of customers with access to premium observability features vs. those without.
Example (hypothetical) scenario: a SaaS provider reduces average trace storage by 40% using sampling and a 30/365 retention split. If baseline telemetry spend was $120k/month, optimizations could reduce spend to ~$72k/month while enabling a paid tier that adds $20k/month ARR. Use a simple ROI calculation: (benefit - delta_cost) / delta_cost to prioritize next investments.
Operational playbook and testing
Include these tests in your runbooks and CI/CD:
- Chaos tests: simulate a noisy tenant and validate rate limits, backpressure and failover.
- Scale tests: synthetic telemetry at 2–3× expected peak across multiple tenant profiles to confirm autoscaling and compaction behavior.
- Security & privacy audits: penetration tests and audits for tenant isolation and data access controls.
- Billing reconciliation tests: sample billing records vs stored usage; reconcile differences in a staging environment.
Common mistakes and how to avoid them
- Unbounded cardinality: prevent by enforcing relabeling, hashing, and limiting accepted label keys at the collector. Validate in CI that new deploys do not introduce new free-form labels.
- Noisy neighbors: enforce per-tenant ingestion and query quotas, and test quota enforcement in controlled chaos runs.
- Late sampling decisions: avoid doing sampling only in downstream stores—do early sampling in the collector to control costs.
- Ambiguous tenant metadata: validate tenant_id at the API gateway and reject or flag telemetry with missing/invalid tenant IDs at ingestion.
- Billing mismatch: build reconciliation jobs and expose explainable usage records so customers can see how charges are calculated.
Pro tips
- Expose a lightweight tenant usage API so customers can monitor their own telemetry spend and adjust behavior (e.g., reduce debug logging).
- Automate relabeling rules and validate them in CI; treat relabeling changes like schema changes with review and testing gates.
- Use precomputed SLI stores for common alerting; derive alerts from compacted data to lower query costs and improve reliability.
- Consider offering “Observability Health” reports to high-value customers as a premium service; these reports can be a strong retention tool.
- Invest in "observability FinOps": cross-functional reviews (SRE + finance + product) every quarter to tune retention, sampling and pricing tiers.
Vendor selection and open-source tradeoffs (updated)
Open-source stacks (OpenTelemetry, Prometheus patterns, Cortex/Thanos, Loki, Tempo) continue to provide maximal flexibility and lower long-term vendor lock-in, but require sustained operational investment. Managed vendors (Grafana Cloud, Datadog, New Relic, Splunk, Honeycomb and others) now offer built-in tenant-aware features, usage metering and KMS integrations that accelerate rollout. Decision factors:
- Time-to-market vs operational control.
- Predictable cost vs per-ingest billing variability (consider negotiated committed-use discounts for heavy telemetry).
- Compliance and residency needs.
- Integration with your billing and identity stacks.
Migration strategy (concise)
- Pilot with internal tenants and a controlled group of external customers.
- Dual-run critical customers during validation, then switch traffic in waves by tier/region.
- Provide migration tooling and a rollback plan; decommission legacy pipelines only after KPIs meet targets.
Final recommendations
For August 2026, most enterprise SaaS providers should adopt a hybrid model: logical multi-tenancy for the long tail, dedicated or isolated slices for large or regulated tenants. Standardize on OpenTelemetry for collection, push tenant-aware decisions into the collector, and treat observability as a costed product with tiered retention, sampling and query SLAs. Pair technical controls with organizational practices—cross-team FinOps reviews, security audits and a migration plan—to turn observability from an expense into a measurable business enabler.
FAQ
How do I decide which tenants need isolated storage or dedicated clusters?
Prioritize tenants by contract and risk: those with explicit legal/regulatory isolation requirements, those responsible for a large share of traffic or telemetry cost, and those willing to pay for isolation. Use cost-per-tenant and telemetry-volume metrics from a pilot to set thresholds (for example, any tenant contributing >X% of ingest or >Y GB/day may qualify for dedicated resources).
Can I avoid buying a managed observability vendor and still scale?
Yes—open-source stacks scale when engineered correctly, but they require investment in operational expertise, autoscaling patterns, and capacity management. If your team lacks SRE capacity, a managed vendor can reduce time-to-market and operational overhead, though at a higher per-ingest cost.
What are the quickest levers to reduce telemetry cost today?
Start with tenant-aware sampling and retention tiering, move debug-level logs to short retention or archival, and implement relabeling to remove high-cardinality labels. Also audit ingestion rates for misconfigured SDKs that emit verbose data (common cause of sudden cost spikes).
How do I prove tenant isolation for audits?
Combine technical and operational evidence: per-tenant encryption keys or KMS scopes, region-specific storage routing, IAM and SCIM provisioning logs, and immutable audit trails showing who accessed tenant telemetry. For sensitive customers, confidential compute processing or dedicated accounts provide stronger guarantees.
What monitoring should I put around the observability pipeline itself?
Track per-tenant ingest rates, storage growth, queuing/backlog length, tail latencies for queries, error rates in collectors and any relabeling anomalies. Alert on sudden cardinality growth, sustained backlogs or multi-tenant query storms. These signals let you act before customers experience degraded SLAs.