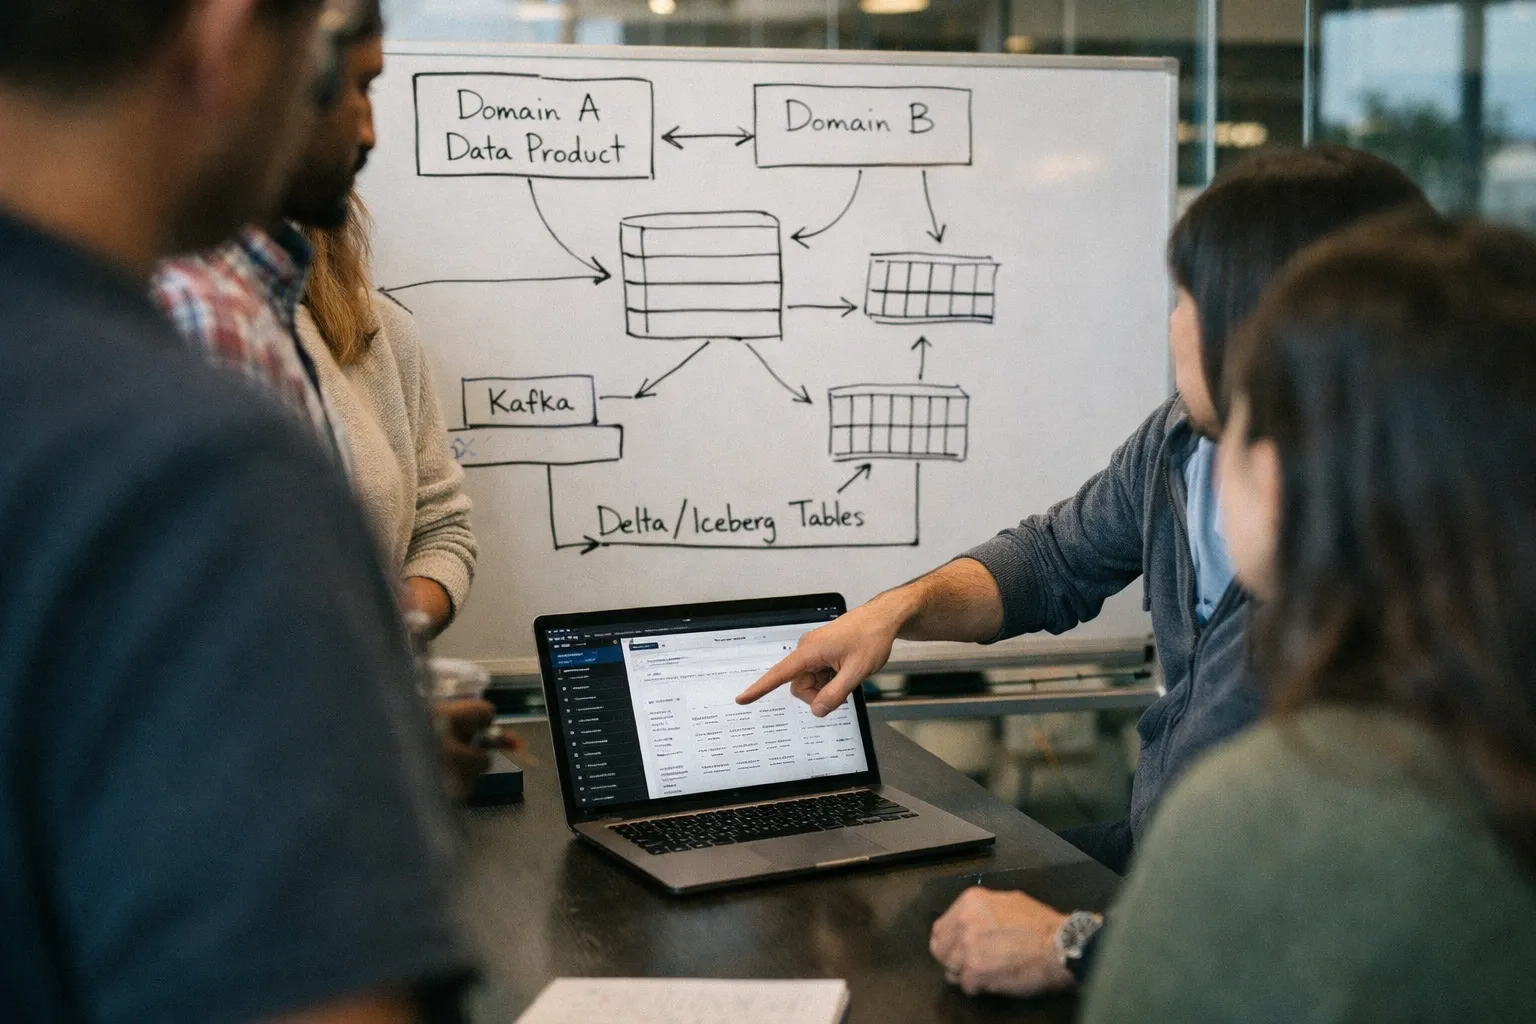
Data mesh has moved from ThoughtWorks white papers to boardroom strategy documents. Large enterprises increasingly treat datasets as products and distribute ownership to domain teams. But turning the concept into production-grade enterprise solutions exposes hard trade‑offs around integration, scalability, cost and measurable ROI. This analysis distills patterns from public case studies and vendor strategies, highlights where organizations overspend or underdeliver, and offers a practical implementation playbook for CIOs and platform leads.
Why data mesh, now?
Two forces are converging. First, scale: monolithic data teams and centralized lakes struggle to keep pace as the number of analytical and operational consumers multiplies. Second, real‑time use cases—fraud detection, personalization, supply‑chain orchestration—demand lower latency and tighter ownership. Data mesh promises local autonomy with shared standards: domain teams own their data products while a central platform provides self‑service infrastructure and governance.
Common enterprise implementation patterns
Implementation varies, but three patterns recur in large deployments:
- Federated domain data products: Domains publish discoverable, versioned datasets (batch or stream) with metadata, schema contracts, and SLAs. Zalando and ING have public writeups describing domain ownership and product catalogs.
- Platform-as-a-service for data teams: A central data platform team provides standardized tooling (streaming, storage formats, catalogs, CI/CD for data) so domains don't solve infra repeatedly. This reduces friction but increases platform costs.
- Federated governance: Policy is centrally coordinated but implemented locally. Governance artifacts—access policies, data contracts, lineage—are enforced via the platform and automated controls.
Technology building blocks
- Event streaming (Apache Kafka, Confluent) for cross‑domain publish/subscribe.
- Lakehouse storage formats (Delta Lake, Apache Iceberg) or columnar object stores for analytics.
- Metadata and cataloging (OpenLineage, Amundsen/Marquez) to enable discovery and observability.
- Data contracts and schema registries to stabilize integration across product versions.
- Self‑serve pipelines and CI/CD for data (infrastructure templates, GitOps for data workflows).
Scalability constraints — where mesh can choke
Data mesh scales ownership but not automatically scalability. Three pressure points appear in real deployments:
- Operational cost explosion: Many domain teams copying identical infrastructure (compute clusters, stream partitions, storage) drives duplicated spend. Centralizing shared services (managed streaming, shared compute pools) is essential to avoid runaway OPEX.
- Integration sprawl: Without strict interface and contract discipline, hundreds of “discovered” datasets become brittle integration points. Enterprises end up with the same integration mess the mesh was supposed to solve—only distributed.
- Cross‑domain consistency: Analytics that require unified joins across domains encounter performance and consistency challenges. Two options emerge: push more integration into the platform with standardized physical storage/layouts, or accept eventual consistency and design queries differently.
Quantifying ROI — what to measure
ROI for data mesh is multi‑dimensional and nontrivial to attribute. Successful programs track a mix of engineering productivity, business outcomes and cost metrics:
- Time‑to‑data/product: Reduction in weeks-to-days for new data products or reports.
- Consumer adoption: Number of downstream consumers and frequency of consumption per data product.
- Data quality and incident reduction: Fewer production data incidents and reduced mean time to recover (MTTR).
- Compute/storage cost per query or per user: Track unit economics as domains add workloads.
- Business KPIs tied to data products: Revenue lift, churn reduction, fraud reduction attributable to specific data products.
Enterprises that instrument these metrics before wide rollout can calculate incremental ROI and make course corrections. Without measurement, “decentralize and hope” becomes expensive experimentation.
Cost trade‑offs: where enterprises overspend
Common cost sinks include:
- Duplicate infrastructure: Small teams spinning up dedicated clusters rather than using shared managed services.
- Excessive data replication: Copying petabytes across zones for locality without evaluating access patterns.
- High‑touch governance manual work: Human reviewers and bespoke connectors slow throughput and inflate staffing costs.
Countermeasures: provide domain‑specific quotas, enforce tiered storage policies, and automate policy enforcement (access control, PII detection) at the platform level.
Integration playbook for robust mesh implementations
Enterprises that succeed treat integration as a first‑class deliverable, not an afterthought. Practical steps:
- Define minimal product contract: Every data product must publish a schema, version policy, SLAs (availability, freshness), and owner contacts. Keep the contract lightweight and automatable.
- Standardize transport and formats: Choose a small set of approved protocols (Kafka topics, Parquet/Iceberg tables, REST/GraphQL endpoints) and enforce them via platform templates.
- Implement observability and lineage: Automated lineage coupled with alerting on contract breaches reduces friction for consumers integrating new products.
- Invest in platform abstractions: Provide SDKs, CLI tools, and managed connectors so domains reuse patterns rather than reinventing them.
- Start with integration patterns, not technology: Map common cross‑domain use cases (real‑time personalization, billing reconciliations) and design template integrations for those flows.
Governance: balance autonomy and control
Federated governance succeeds when policy is automated and incentives align. Concrete governance levers:
- Automated policy enforcement (data masking, retention) embedded in the platform.
- Domain SLAs tied to consumption‑based charges or credits to incentivize quality.
- Cross‑functional governance board that includes domain product owners, platform engineers, legal, and security to arbitrate standards and exceptions.
Case signals: what success looks like
Successful enterprises tend to share a few traits:
- A small set of platform engineers delivering reusable infra components (not endless custom requests).
- Clear measurement: adoption, time‑to‑product, and cost per data product tracked monthly.
- Controlled rollout: pilot with 2–4 domains, refine contracts and tools, then expand.
Zalando and ING — among public early adopters — emphasize building catalogues of discoverable data products and platform APIs to reduce friction. Their early playbooks also highlight iterative rollouts and investment in automation.
When not to adopt a full mesh
Not every enterprise should rip out centralized architectures. Consider delaying or qualifying mesh adoption when:
- Data sets are small and infrequently used; centralized analytics teams are meeting SLAs.
- Regulatory or compliance needs mandate centralized control of certain datasets.
- Organizational readiness is low: no platform team, no product owners for data, and limited automation capability.
Conclusion — pragmatic steps for CIOs and platform leaders
Data mesh is valuable as a set of organizational and technical patterns, but it is not a silver bullet. To extract ROI from enterprise solutions built on mesh principles, organizations must:
- Instrument ROI and operational metrics from day one.
- Invest in a robust self‑service platform to avoid duplication and contain OPEX.
- Enforce lightweight, automated integration contracts and observability.
- Start small, measure often, and expand once unit economics are proven.
When treated as a pragmatic engineering and governance program—rather than a buzzword—data mesh can improve scalability, accelerate time‑to‑insight and increase developer productivity. The alternative is expensive fragmentation: many domain teams, many datasets, and unclear value. The implementation choices you make in the first pilots determine whether data mesh becomes a scalable enterprise solution or a costly integration problem.