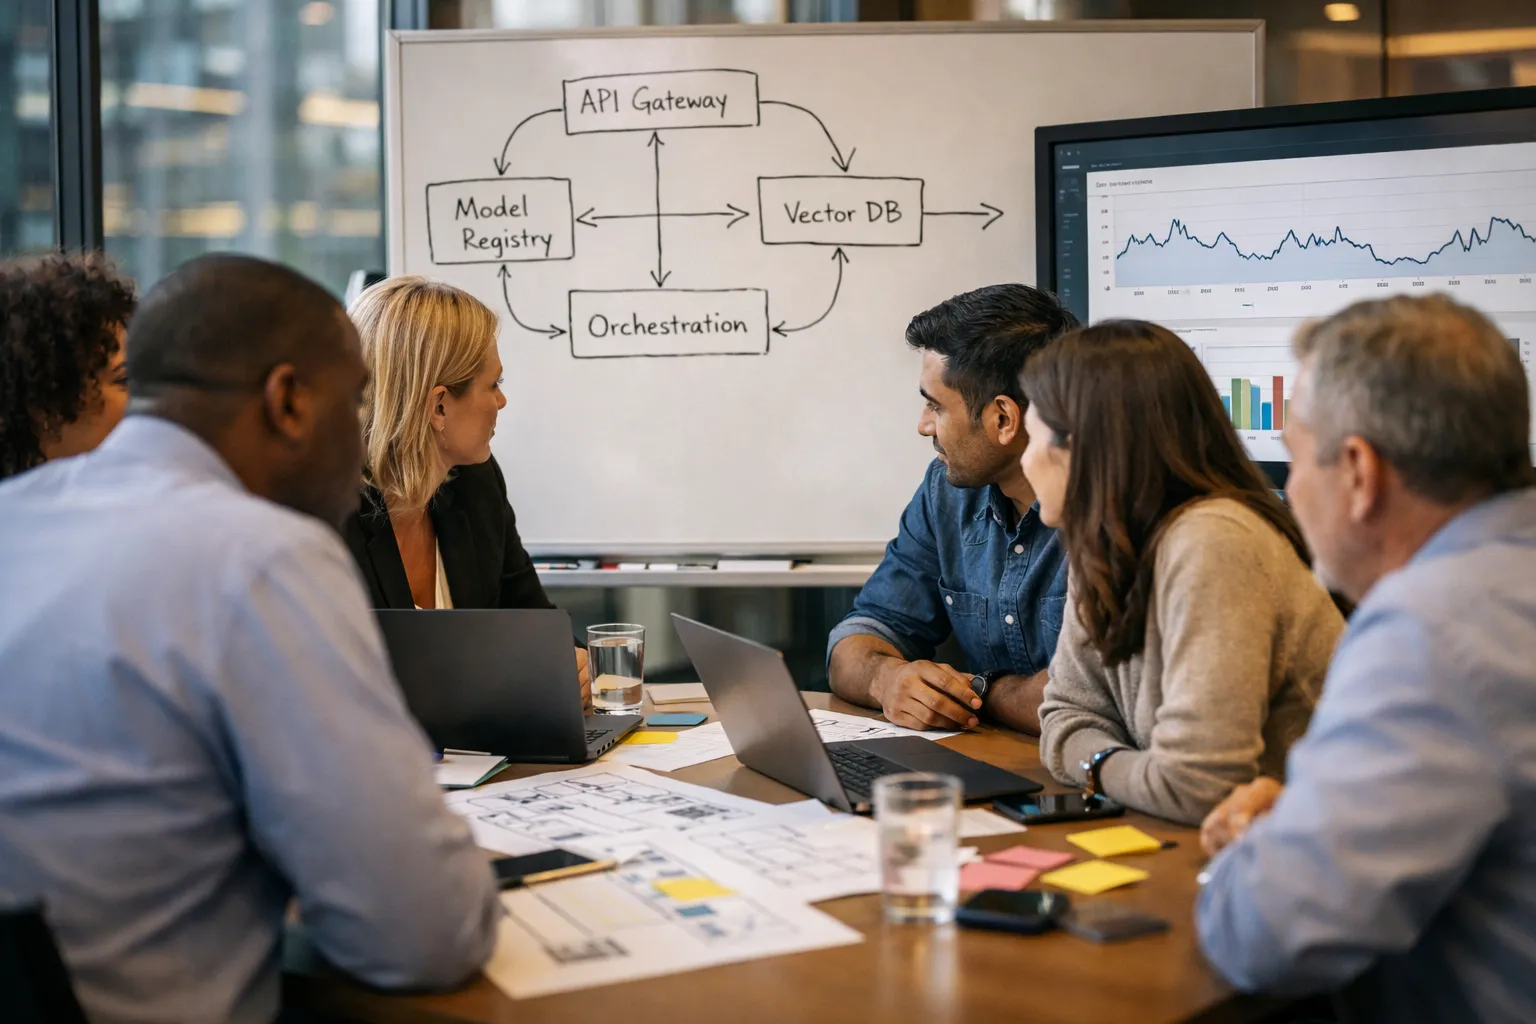
Large language models (LLMs) have moved from lab experiments to core enterprise solutions in 2026. But packaging an LLM into a secure, scalable, integrated platform that delivers measurable ROI requires discipline: architecture choices, data governance, cost controls, and phased implementation. This guide walks enterprise software teams through a pragmatic LLMops implementation—design, integration patterns, scalability techniques, governance, ROI modeling, and a practical rollout roadmap.
Why build an enterprise LLM platform?
Enterprises look for standardized, repeatable ways to embed generative AI into applications: customer service assistants, contract analysis, code generation, knowledge discovery, and automated insights. A central LLM platform turns ad hoc models into enterprise solutions by delivering:
- Consistent integration points for diverse applications and teams
- Governance, monitoring, and model lifecycle management
- Scalability across users, tenants and workloads
- Cost controls, reuse of embeddings and caching to improve ROI
Core principles for enterprise LLMops
Designing the platform around these five principles reduces risk and accelerates value:
- Composable integration: expose the platform via stable APIs, event adapters and SDKs for microservices alignment.
- Data-aware security: integrate with existing IAM, DLP, and SIEM for sensitive data controls.
- Model governance: versioning, lineage, evaluation metrics and approval workflows for models and prompts.
- Scalability and cost efficiency: autoscaling inference, batching, model cascades and vector index sharding.
- Measurable ROI: define KPIs tied to time-to-value, cost-per-request and business outcomes before implementation.
High-level architecture
An enterprise LLM platform typically contains these components. The architecture below focuses on integration and scalability.
1. Front layer: API and orchestration
- REST/gRPC API gateway, authentication (OAuth2/SAML via enterprise IAM), rate limits and request routing.
- Orchestration service (workflow engine) to manage multi-step prompts, tool calls, and long-running tasks.
2. Model and serving plane
- Model registry with metadata, canary deployment and rollback capabilities.
- Inference fleet: GPU/accelerator pools for high-throughput low-latency serving; CPU-based servers for small models or fallback.
- Model cascade orchestration: cheap small models for classification, larger models for synthesis to optimize cost and latency.
3. Retrieval and embeddings layer
- Vector database(s) for embeddings (sharded, region-aware) and retrieval augmentation (RAG).
- Index lifecycle management: incremental indexing, compression, TTL policies for stale content.
4. Integration and data plane
- Adapters/connectors to enterprise data sources: document stores, data warehouses, CRM, ticketing systems.
- Streaming ingestion (Kafka or managed alternatives) for near-real-time content updates.
5. Observability, governance and cost control
- Telemetry for latency, throughput, token usage, hallucination rate, user satisfaction and channel-specific KPIs.
- Policy engine for content filtering, redaction and regulatory controls (e.g., EU data residency).
- Cost monitoring, tagging by tenant/business unit, and automated scaling policies tied to budget thresholds.
Integration patterns
Choose patterns based on latency tolerance, data sensitivity and scale.
1. Synchronous API embedding (low-latency UI flows)
Direct API calls to the platform for chatbots, search assistants or in-app help. Use short-context prompts, caching of recent responses, and adaptive throttling.
2. Asynchronous event-driven integration
For document processing, background summarization and batch enrichment, use events to trigger pipeline jobs. This decouples ingestion from inference and improves reliability at scale.
3. Hybrid retrieval-augmented generation (RAG)
Combine a retrieval step (query vector DB) with LLM generation to ground outputs. Keep the retrieval system close to source data and ensure embeddings pipeline supports incremental updates.
4. Safe tooling and function calls
Use controlled tool invocation for tasks needing deterministic behavior (DB lookups, invoice payments). Ensure the orchestration layer mediates tool access and logs actions.
Scalability techniques
To meet enterprise SLAs and control costs:
- Autoscaling pools: separate inference pools by latency class and scale independently.
- Model cascade: route simple prompts to cheap models and escalate only when needed.
- Batching and micro-batching: group inference calls to increase GPU utilization for throughput-oriented workloads.
- Edge vs cloud placement: place inference near data residency or latency needs—hybrid deployments are common.
- Embedding reuse and cache: cache retrieval results and share embeddings across applications to lower repeated compute.
- Sharded indexes: partition vector DBs by tenant or topic to improve query latency at scale.
Governance, compliance and security
Enterprise adoption hinges on trust. Implement these controls:
- Data classification and masking in ingestion pipelines; treat embedding generation as a transformation that may require consent.
- Model explainability logs (prompt + context + model version + response) retained per retention policy and available for audit.
- Access controls integrated with enterprise IAM, with least privilege applied to model operations and tooling.
- Regular model evaluation suites including bias, toxicity and hallucination tests—run on production traffic samples.
- Data residency and export controls enforced at connector and storage layers.
ROI modeling: making the business case
Define ROI using three pillars: cost reduction, revenue enablement, and risk avoidance. Establish baseline metrics before pilot.
Example ROI calculation (hypothetical)
Use this template to estimate first-year impact.
- Use case: Automated contract triage for legal intake.
- Volume: 120,000 contracts/year.
- Baseline cost: 20 minutes manual review per contract at $60/hour => 20/60*60 = $20 per contract; annual cost = $2.4M.
- Post-LLM: automated triage + human review reduces manual time to 5 minutes => $5 per contract; annual cost = $600k.
- Gross labor savings = $1.8M/year.
- Platform costs: inference, storage, infra, and ops = $300k/year (includes reserved capacity, vector DB, monitoring).
- Net savings Year 1 = $1.5M. Payback period 1 year given pilot-to-production transition.
Adjust assumptions for accuracy: error rates requiring human remediation, model retraining costs, and compliance overhead.
Implementation roadmap
Use a phased approach with clear entry/exit criteria. Typical timeframe: pilot 8–12 weeks, production rollout 3–9 months, enterprise scale 12–24 months.
Phase 0: Preparation (2–4 weeks)
- Define use cases, business KPIs, security and compliance constraints.
- Inventory data sources and integration points.
- Establish sponsorship, budget and cross-functional team (platform, security, data engineering, business owners).
Phase 1: Pilot (8–12 weeks)
- Build a minimal viable LLM pipeline for 1–2 high-impact use cases (RAG for policy search, automated triage, or customer support automation).
- Implement basic monitoring, cost tracking and governance playbooks.
- Measure ROI signals (time saved, accuracy, user satisfaction).
Phase 2: Productionize (3–6 months)
- Harden connectors, add model registry, implement versioning and CI/CD for model/prompts.
- Iteratively optimize inference costs using model cascades, batching and caching.
- Rollout to additional teams and integrate with enterprise IAM and SSO.
Phase 3: Scale and operationalize (6–18 months)
- Introduce multi-tenant support, chargeback reporting and advanced observability.
- Automate retraining pipelines and continuous evaluation on production data.
- Formalize governance, change control and incident playbooks.
Operational metrics and dashboards
Track these KPIs from day one:
- Business: time saved, tasks automated, revenue impact, error rate reduction.
- Model: perplexity/ROUGE/F1 on labeled datasets, hallucination rate, prompt success rate.
- Platform: requests/sec, P95 latency, cost per 1k requests or per 1M tokens, GPU utilization, cache hit ratio.
- Governance: number of flagged outputs, policy violations, audit log completeness.
Common pitfalls and how to avoid them
- Scope creep: Start with narrow, measurable pilots tied to ROI and expand incrementally.
- Underestimating integration effort: Prioritize building robust connectors and align with data engineering roadmaps early.
- No governance runway: Define policies and auditability before going wide; remediation is far harder later.
- Ignoring cost controls: Model selection and serving patterns must be driven by business SLAs and cost guardrails.
Practical checklist before go-live
- Confirmed business KPIs and sponsor sign-off.
- Authentication and authorization integrated with enterprise IAM.
- Data classification and DLP rules applied to ingestion and embeddings.
- Model registry and CI/CD for model/prompts established.
- Observability and cost dashboards live with alerting.
- Runbook for incidents and rollback procedures documented and tested.
- Pilot success validated against predefined exit criteria (accuracy, cost, user satisfaction).
Closing: strategy to capture sustained ROI
In 2026, enterprise LLM platforms are not a black-box utility; they are strategic platforms that require the same rigor as any core enterprise solution. Successful implementations align integration, governance, scalability and clear ROI measurement. Start small with a tightly scoped pilot, instrument business and technical metrics, and iterate toward a composable, governed platform that integrates cleanly with the rest of your enterprise stack.
When you treat an LLM platform as an enterprise solution—designing for integration from day one, architecting for scalability, and enforcing governance—you create a foundation that delivers measurable ROI while minimizing operational and compliance risks.