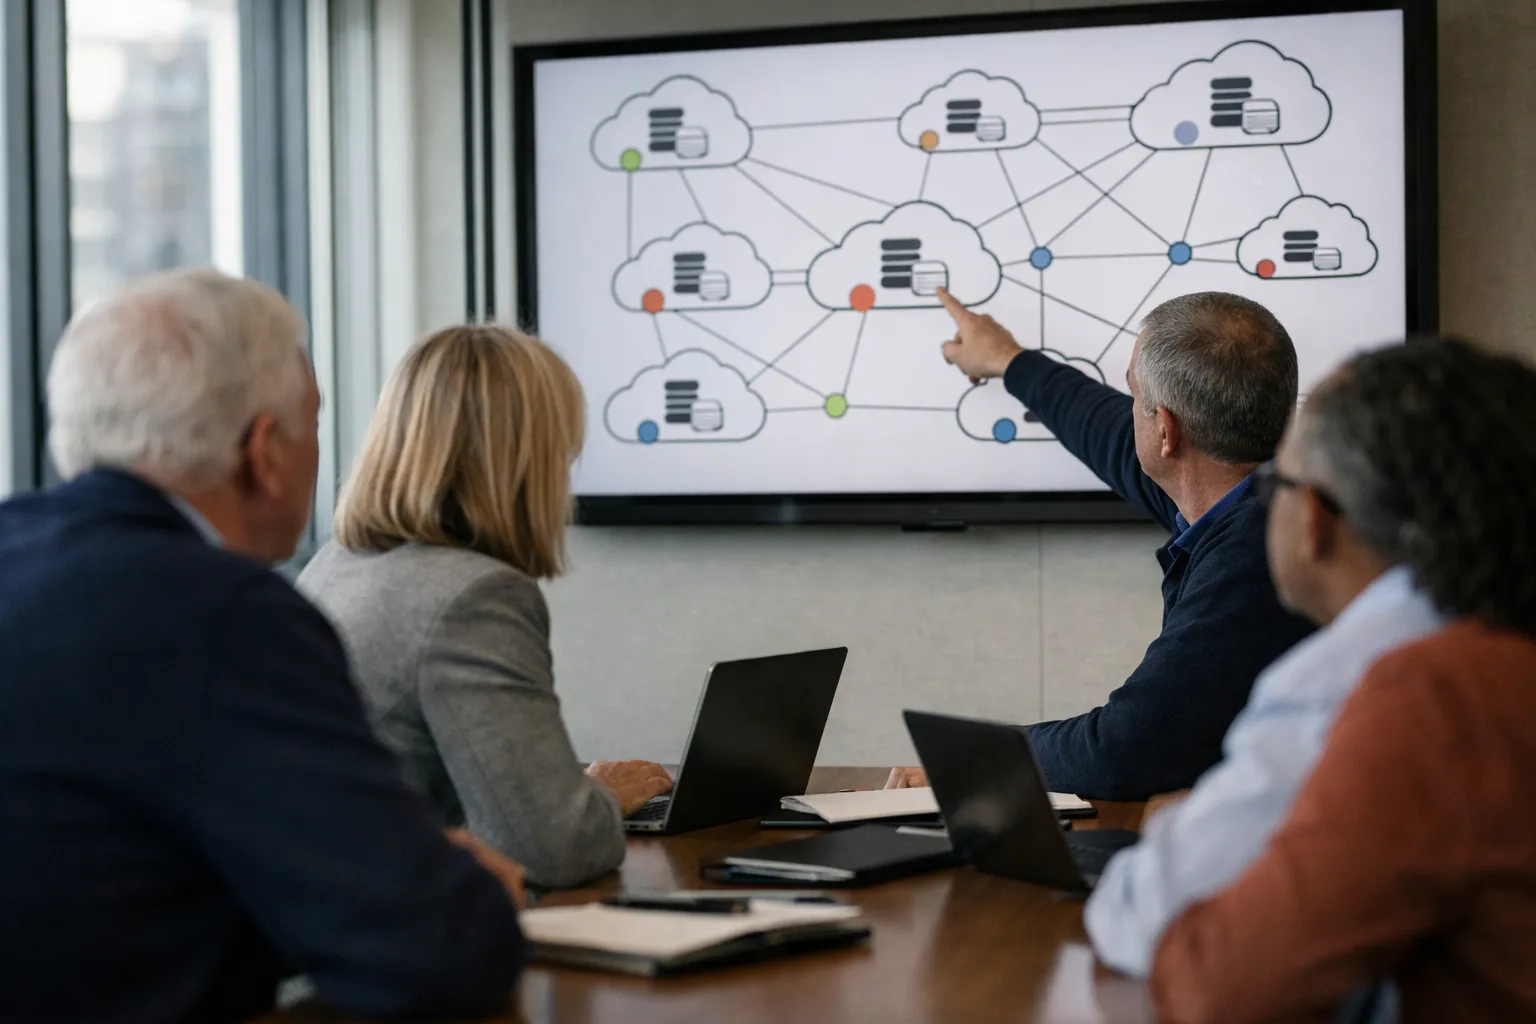
As enterprises push transactional workloads beyond single-region boundaries and legacy RDBMS limits, Distributed SQL has become a mainstream option for stateful enterprise solutions. In 2026 the market has matured: major vendors offer turnkey cloud services and open-source distributions, and architectural patterns for adoption are better understood. Yet choice remains non-trivial. This analysis parses the technical trade‑offs and business implications enterprises must weigh—scalability, integration, implementation effort, and ROI—so technology leaders can make a defensible selection.
What "Distributed SQL" means today
The term describes systems that combine SQL semantics and ACID transactions with horizontal, multi-node scaling. Implementations vary: fully managed global databases (true single‑system abstractions), self-managed clustered databases, or cloud‑native variants offering regional replicas. Key capabilities to compare are distributed transactions, consistent reads, horizontal rebalancing, and SQL-standard compatibility. These attributes determine whether a product fits an enterprise's workload profile and integration surface.
Primary technical trade-offs
Consistency vs latency
Distributed SQL vendors make different consistency and replication choices. Strongly consistent, synchronous replication preserves ACID semantics across zones but incurs higher cross‑region tail latency. Some vendors provide tunable consistency modes or hybrid approaches (single‑region strong commits with async cross‑region replicas). Enterprises must map tolerance for read/write latency to business requirements: high‑frequency payments or stock trading demand strict consistency; regional e‑commerce catalogs may accept eventual cross‑region convergence for lower latencies.
Scalability model: scale‑out compute vs scale‑out storage
Scalability is not monolithic. Some databases scale by adding compute-only nodes and separating storage (disaggregated storage), enabling near‑linear throughput growth for stateless query processing. Others require adding nodes that carry both compute and storage, which simplifies architecture but increases rebalancing overhead. Understand whether your anticipated growth is compute‑bound (transaction throughput) or storage‑bound (large datasets, wide row counts) and choose a model that minimizes rebalancing windows and operational friction.
SQL compatibility and developer ergonomics
Vendor SQL dialects and ecosystem integration vary. JDBC/ODBC compatibility, ORM behavior (Hibernate, ActiveRecord), and support for procedural extensions influence migration effort. A product with a high degree of compatibility reduces application refactor work, a major driver of implementation cost.
Operational maturity and tooling
Operational features—backup/restore, point‑in‑time recovery, schema migrations, monitoring integrations, and automated failover—make or break production readiness. Enterprises should evaluate whether operational tooling integrates with existing observability stacks and runbooks. Poor tooling increases staff time and hidden operational cost, reducing ROI.
Integration patterns and migration approaches
Enterprises rarely rip and replace monolithic databases. Common, proven integration patterns in 2026 include:
- Dual‑write with reconciliation: Application writes to legacy RDBMS and Distributed SQL in parallel for a bounded cutover window, using idempotent writes and reconciliation jobs to resolve drift.
- Write‑side gateway: A middleware layer routes transactions to the appropriate system (new vs legacy) during phased migration, centralizing integration logic and observability.
- Event‑driven migration: Source DB emits change events (CDC) consumed to populate Distributed SQL, with eventual cutover after verification.
Each pattern carries implementation complexity. Dual‑write risks divergence and requires robust reconciliation; CDC pipelines demand integration with enterprise messaging infrastructure; write gateways centralize complexity and must themselves be highly available.
Implementation phases and common pitfalls
- Proof of concept (PoC): Validate core transactional guarantees under representative load and failure modes—network partitions, zone failures, node restarts.
- Schema and workload tuning: Distributed topologies may change optimal data modeling—consider primary key strategy, partitioning, and indexing to minimize cross‑partition transactions.
- Operational runbook development: Update incident response, maintenance windows, and capacity planning to reflect distributed behaviors (rebalancing, cross‑region bandwidth).
- Phased migration: Start with bounded services (non‑critical domains) to refine migration tooling and estimate real implementation cost for broader rollouts.
Common pitfalls that derail projects: underestimating cross‑region egress costs, neglecting schema redesign, failing to measure tail latency under failure scenarios, and assuming plug‑and‑play compatibility with existing ORMs or stored‑procedure logic.
ROI considerations: capex, opex, and business value
ROI for Distributed SQL is a blend of direct cost and strategic value. Cost drivers include licensing/subscription fees, cloud egress and I/O costs, and operational staffing. However, savings and value accrue from reduced application complexity (eliminating bespoke sharding middleware), improved availability, and faster time to market for globally distributed features.
Decision-makers should model TCO across a 3‑ to 5‑year horizon, quantifying:
- Migration implementation cost (development, testing, data transfer).
- Ongoing run costs (compute, storage, egress, support).
- Operational staffing and training.
- Business benefits: fewer incidents, faster feature delivery, reduced custom sharding maintenance.
Enterprises that underweight integration and implementation costs often see delayed or negative ROI. Conversely, those that prioritize alignment between workload characteristics and a vendor’s strengths realize cost and agility gains within the first 18–24 months.
Vendor positioning and real‑world signals
By 2026 the landscape clusters vendors by operational model: fully managed global services that abstract topology, self‑managed clustered databases for on‑premises or hybrid clouds, and cloud‑native disaggregated systems optimized for hyperscalers. When evaluating vendors, look beyond marketing claims to:
- Evidence of sustained multi‑region production deployments and published failure scenarios.
- Third‑party benchmarks aligned with your workload patterns (not just synthetic tps numbers).
- Reference architectures for integration with enterprise identity, backup, and monitoring systems.
Enterprises also should check contractual details: SLAs that account for cross‑region consistency, support escalation paths, and clear pricing for cross‑region egress and data movement.
Guidelines for enterprise selection
Make the choice defensible with a short matrix that maps workload attributes to vendor capabilities:
- If you require global strong consistency for financial/ledger workloads, prioritize vendors with low‑latency consensus protocols and predictable tail latency.
- If you expect rapid, linear throughput growth, validate proven scale‑out compute models and non‑disruptive rebalancing.
- If minimal application change is critical, prioritize SQL and ecosystem compatibility and test ORMs, JDBC drivers, and stored procedure behavior early.
- If integration with existing backup/DR and observability stacks matters, choose vendors with mature tooling and documented runbooks for enterprise solutions.
Conclusion
Distributed SQL has matured into a practical choice for many enterprise transactional workloads in 2026, but selection is not commodity shopping. Successful adoption depends on matching technical trade‑offs—consistency, partitioning, and operational models—to business priorities, and on realistic accounting for integration and implementation costs. Enterprises that invest in a rigorous PoC, plan phased migrations, and align vendor features with concrete ROI metrics will extract the most value from Distributed SQL while avoiding common pitfalls that inflate costs and delay benefits.