Introduction — What you'll learn and who this is for
This guide explains how to implement, operate, and justify change-data-capture (CDC) pipelines using Debezium and Apache Kafka in an enterprise environment as of July 2026. It is written for platform engineers, integration architects, and technical product managers who must move transactional changes to analytics, search, caches, and service fabrics with low latency, correctness, and governance. You will get step-by-step implementation guidance, updated best practices reflecting 2026 operational realities (multi-cloud managed services, workload identity, OpenTelemetry integration), and a practical ROI framework you can use in procurement conversations.
Prerequisites and context — What you should know first
Before you begin:
- You and your DBAs must know whether source systems can support logical decoding or change streaming (Postgres logical decoding, MySQL binlog, Oracle/SQL Server CDC equivalents).
- Your organization should have a Kafka strategy (self-managed vs managed) and basic platform capabilities: k8s, secrets management, and observability stack.
- Basic familiarity with Debezium connectors, Kafka topics/partitions, and stream processing (ksqlDB, Kafka Streams, Flink/Materialize-like engines) will help.
Why this matters now (July 2026): managed Kafka providers have standardized support for managed Connect workers and tiered storage; enterprises increasingly require strict data residency, workload identity (SPIFFE/SPIRE or cloud-native equivalents), and end-to-end observability (OpenTelemetry). Those operational shifts change deployment choices and cost models compared with early CDC projects.
Why choose CDC with Debezium + Kafka in 2026?
CDC remains the pragmatic way to stream row-level changes from OLTP systems into downstream consumers. In 2026, the pattern is strengthened by:
- Mature connector ecosystems: Debezium and vendor connectors cover most relational and some NoSQL systems with better schema handling and error modes.
- Managed operational primitives: Most cloud providers and independent vendors now offer managed Kafka with Connect-as-a-service and tiered/cold storage, reducing ops overhead for large retention or compliance needs.
- Better observability & tracing: Integration with OpenTelemetry and distributed tracing makes event lineage and troubleshooting across CDC pipelines practical.
- Enterprise security practices: Workload identity, short-lived credentials, and platform RBAC are standard, simplifying secrets management for connectors.
When CDC is the right decision (and when it’s still not)
Choose CDC when you need:
- Near-real-time updates to downstream systems (sub-second to few-seconds latency).
- A single event source to serve multiple consumers (analytics, search, caches, microservices).
- Ordering guarantees for an entity key (enforced via partitioning).
Reconsider CDC when:
- Use cases are simple bulk syncs with strict global reconciliation that batch ETL already satisfies better and cheaper.
- Source DBs cannot safely support logical log reads or the vendor disallows it for security/performance reasons.
- Your organization lacks platform maturity and governance; in that case evaluate managed Kafka Connect offerings or partner with a platform team first.
High-level architecture and modern components
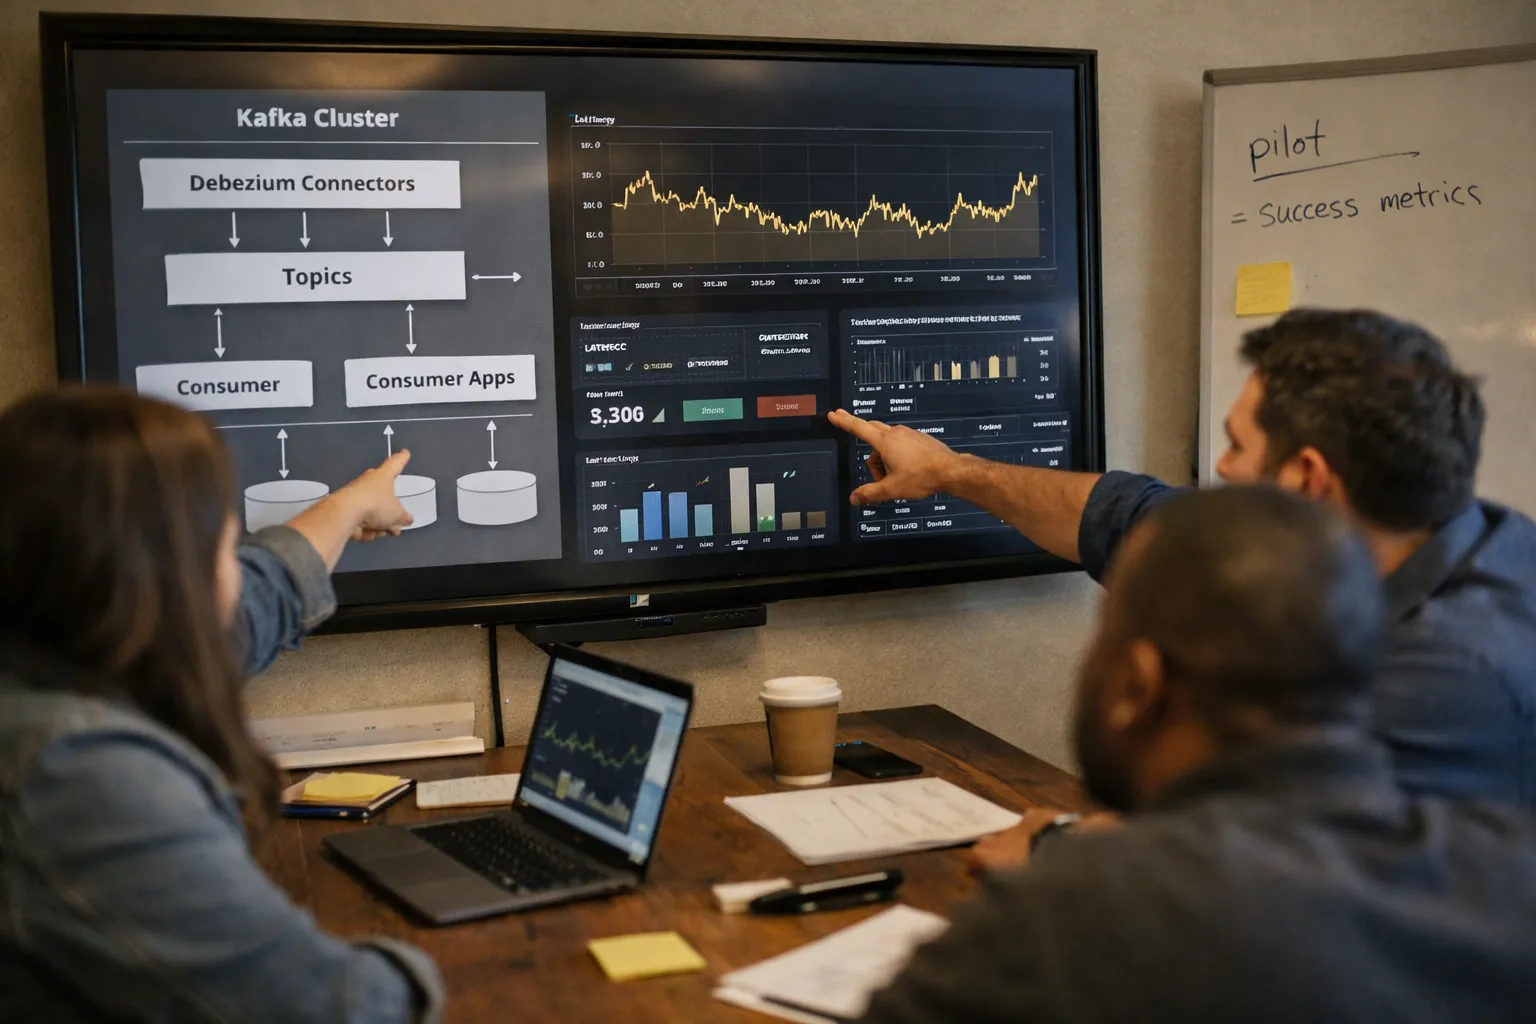
Typical enterprise CDC architecture in 2026:
- Source databases that expose transaction logs or native CDC APIs.
- Debezium (or vendor) connectors running as managed Connect workers or self-hosted Kafka Connect clusters; connectors emit standardized change events.
- Kafka cluster (self-managed, Confluent Cloud, MSK/Amazon, Aiven, or other provider) with tiered/cold storage options and multi-region replication where required.
- Schema registry for Avro/Protobuf/JSON Schema contracts; policy enforcement for compatibility and governance.
- Stream processing layer (ksqlDB, Kafka Streams, Flink, Materialize-style systems) to filter, enrich, and produce derived business events or materialized views.
- Downstream sinks: data warehouses or lakehouses (Snowflake, BigQuery, Databricks), S3-compatible object stores, search indexes, caches, and microservices.
- Observability: Prometheus/Grafana metrics, logs, OpenTelemetry traces, and lineage tools to correlate DB commit → connector → topic → consumer processing.
- Governance: topic ACLs, IAM/workload identity, audit logs, DLP masking and data residency controls.
Step-by-step implementation
1. Define scope and measurable success criteria
- Select a small, high-value pilot: 1–3 transactional tables or a single business domain (orders, accounts, inventory).
- Define clear metrics: end-to-end latency target (for example 5s median, 30s 99th), data completeness (pair counts per transaction window), and business KPIs (reduced reconciliation time, faster fraud detection).
- Include operational objectives: connector restart time, mean time to recover (MTTR), and acceptable cloud storage spend for retention.
Why: a constrained pilot reduces unknowns (schema drift, connector tuning) and produces measurable outcomes for stakeholders.
2. Verify source DB capabilities and plan connector configuration
- Document DB version, logical decoding settings, replication slot impacts, and transaction log retention requirements. Example: Postgres requires wal_level=logical and sufficient WAL retention to prevent connector lag-induced slot deletion.
- Coordinate with DBAs to schedule initial snapshot windows and to test connector load on replicas rather than primaries where possible.
- Plan connector security: use short-lived credentials, least-privilege roles, and run Connect workers in the same VPC/region to reduce network egress.
Why: early alignment with DBAs prevents surprise operational impact and data loss from rotated logs or checkpoints.
3. Choose a deployment model for Kafka and Connect
- Evaluate managed vs self-managed on three axes: operational team capacity, compliance (data residency, audit), and cost predictability.
- If using managed Kafka, prefer offerings that provide managed Connect and tiered storage if you expect long retention or regulatory archives.
- For self-hosted, consider operators like Strimzi on Kubernetes and use immutable infrastructure patterns to simplify upgrades.
Why: in 2026, managed providers reduce toil for enterprises that lack large platform teams; self-managed options retain maximum control for regulated environments.
4. Design topic model, partitioning, and schema management
- Decide topic-per-table vs topic-per-aggregate: topic-per-table is simpler for schema evolution; topic-per-aggregate (logical groupings) can match downstream consumers better.
- Choose partition key aligned with ordering and hotspot risk — use natural keys (customer_id, order_id) and avoid high-cardinality columns that cause hot partitions.
- Adopt a schema registry with enforced compatibility rules. In 2026, Protobuf and Avro remain strong choices for compactness and contract safety; JSON Schema is still useful when flexibility is prioritized.
Why: good topic/partition design prevents expensive repartitioning and preserves ordering guarantees consumers rely on.
5. Add stream processing, enrichment, and materialized views
- Use stream processing to filter noise (drop irrelevant columns), generate business events, and produce compacted state topics for lookups.
- Consider materialized view engines (ksqlDB or similar) to maintain derived datasets for low-latency reads—this reduces downstream load and simplifies consumer logic.
- Keep enrichment idempotent and cache reference data in compacted topics rather than pulling external DBs on every event.
Why: pushing business logic into the stream avoids duplicated logic across consumers and scales derived datasets more predictably.
6. Integrate downstream systems with idempotency and cost control
- Implement idempotent consumers or use Kafka transactions for sinks that support exactly-once semantics; otherwise design idempotent upserts at the sink.
- For data lake/warehouse loads, batch events and use manifest-based loading to reduce API calls and control egress costs, particularly in multi-cloud setups.
- Control retention and tiering policies per topic to limit storage costs for high-volume streams.
Why: these choices reduce duplicated processing, API costs, and risk of inconsistent sinks.
7. Observability, governance, and testing (non-negotiable)
- Integrate metrics, logs, and traces: instrument connectors and stream processors with Prometheus metrics and OpenTelemetry traces to correlate an event’s path end-to-end.
- Set up dead-letter queues and monitoring alerts for schema errors, connector backpressure, and consumer lag anomalies.
- Run automated tests: use testcontainers or staged clusters for schema evolution tests, connector failover, and rebalancing scenarios. Add chaos testing for replication and connector restarts.
Why: you can’t manage what you don’t measure—end-to-end traces and DLQs make troubleshooting and compliance audits practical.
Scalability and performance considerations (2026 operational tips)
- Partition strategy: Align partition count with expected throughput and consumer parallelism. Use top-level planning: partitions = parallelism × expected peak throughput per partition.
- Connector scaling: Debezium connector concurrency still maps to DB topology — use read replicas, logical sharding, or multiple connector instances for very large tables.
- Tiered/cold storage: Leverage provider tiering for long-term retention; keep hot topics compact and move older segments to cold storage to control cost.
- Backpressure and retries: Configure bounded retries and dead-letter handling; instrument retry counters to catch systemic issues early.
Security, compliance and governance — updated controls for 2026
- Use workload identity (SPIFFE/SPIRE or cloud IAM Workload Identity) so connectors do not store long-lived credentials. Rotate any required DB credentials automatically.
- Encrypt in transit (mTLS) and at rest. Apply topic-level ACLs and integrate with enterprise SSO and RBAC systems.
- Apply data residency controls: pin connectors and topics to required regions, and use tiered storage that can meet archive compliance.
- Use schema registry enforcement, field-level masking, and differential access controls for PII and regulated fields.
Common pitfalls and how to avoid them
- Underestimating cardinality: Track number of tables and partitions and implement retention/compaction policies from day one.
- Schema drift surprises: Enforce compatibility policies and have a staging pipeline to test evolution before prod rollout.
- Cost surprises from egress or retention: Model cloud egress and storage costs; use local processing and compaction to reduce cross-region transfers.
- Poor observability: Without traces and DLQs, debugging is manual and slow—invest early in telemetry integration.
- Running connectors on primaries: Always validate connector load on read replicas where feasible and test snapshot impact during maintenance windows.
Measuring ROI: updated framework and worked example
ROI is still (Total Benefits − Total Costs) / Total Costs over a chosen horizon (3 years is common). Update your model with 2026 variables:
- Managed service premiums (if chosen) and expected savings from reduced platform headcount.
- Cloud egress and tiered storage costs for long retention or multi-region replication.
- Operational risk reduction (fewer reconciliation incidents, faster incident response) converted to dollar impact.
Example conservative first-year pilot (mid-sized enterprise):
- Benefits: Faster detection & prevention of revenue leakage = $500,000; developer/productivity gains = $175,000.
- Costs: Managed Kafka + Connect + monitoring = $325,000; initial integration & consultancy = $200,000.
First-year totals: Benefits = $675,000. Costs = $525,000. ROI = (675k − 525k)/525k = 28.6%. Expect ROI to improve in years 2–3 as one-time costs amortize and additional consumers subscribe to existing topics.
Why this matters: show conservative numbers to procurement and include sensitivity ranges for retention costs and scale assumptions. Include clear KPIs (latency, completeness, MTTR) in contracts or SLOs when working with managed vendors.
Rollout checklist (practical)
- Confirm DB logical decoding capabilities and replication resource impacts.
- Run a small pilot with 1–3 tables and measurable success criteria; test failover and snapshots.
- Establish schema registry and compatibility rules.
- Deploy observability: metrics, logs, traces, and DLQs from day one.
- Perform chaos tests for node failures, connector restarts, and network partitions.
- Document runbooks for connector restarts, consumer lag remediation, and retention management.
- Plan staged expansion by business domain to contain complexity and align with product roadmaps.
Real-world context — what changed by July 2026
By mid-2026, enterprises that invested early have moved CDC from experiments to platform capabilities. Key shifts to account for:
- Managed providers now commonly include Connect-as-a-service and tiered storage; this reduces ops friction but introduces procurement and compliance checkpoints.
- OpenTelemetry adoption for tracing has matured; tracing a database commit to downstream materialized view is now feasible for many teams.
- Workload identity and short-lived credentials are standard practice; secrets-in-config is increasingly unacceptable for regulated environments.
Practical takeaway: choose a deployment that aligns with your compliance and platform maturity, instrument end-to-end, and make ROI conservative and measurable.
Common mistakes recap
- Starting with too many tables. Start small and expand by domain.
- Ignoring schema contracts. Use a schema registry and enforce compatibility.
- Relying on long-lived credentials. Use workload identity and secret rotation.
- Skipping end-to-end testing. Automate schema and failover tests before production.
Pro tips
- Use compacted topics for entity state and regular topics for change streams—this combination reduces downstream lookup latencies and storage.
- Keep high-cardinality columns out of partition keys; use salt-based partitioning only after measuring the hotspot risk.
- Instrument each connector with OpenTelemetry spans and correlate them with Kafka message keys for effective troubleshooting.
- When using managed Kafka across regions, measure cross-region replication costs distinctly and evaluate whether local processing can reduce egress.
FAQ
Do I need a schema registry for CDC?
Yes for production systems. A schema registry enforces compatibility rules, reduces consumer breakage, and supports compact serialization formats (Avro/Protobuf) that are more efficient and safer for evolution than free-form JSON.
Can Debezium handle high-volume tables?
Yes, but connector scalability depends on the source DB topology. For very large tables you may need multiple connector instances, read replicas, logical partitioning, or a hybrid approach that streams high-volume hot partitions separately.
Is managed Kafka always cheaper operationally?
Not always cheaper in pure dollar terms, but managed Kafka reduces platform headcount and operational risk. For regulated workloads or extreme customization, self-hosting can still be the right choice—but model TCO including team cost and incident risk.
How do I prevent PII from leaking through CDC streams?
Apply field-level masking at the connector or stream-processing layer, enforce ACLs for topics containing sensitive fields, and use schema registry policies to block or transform PII fields before they reach downstream consumers.
What are sensible retention policies for CDC topics?
Use short hot retention (days) for high-throughput topics and move older data to cold/tiered storage for compliance or historical analysis. Compact state topics used for lookups typically retain the last value per key indefinitely.
Conclusion
CDC with Debezium and Kafka remains a leading pattern for real-time enterprise integration in July 2026. The core technical decisions are unchanged—start small, design topics and partitions carefully, enforce schemas, and instrument end-to-end—but modern operational realities (managed Connect, workload identity, OpenTelemetry tracing, and tiered storage) make production deployments more practical and auditable. Use conservative ROI forecasts, automate tests and chaos scenarios, and align rollout by business domain to scale sustainably. With governance and observability in place, CDC transforms transactional systems into real-time, reusable enterprise data platforms.