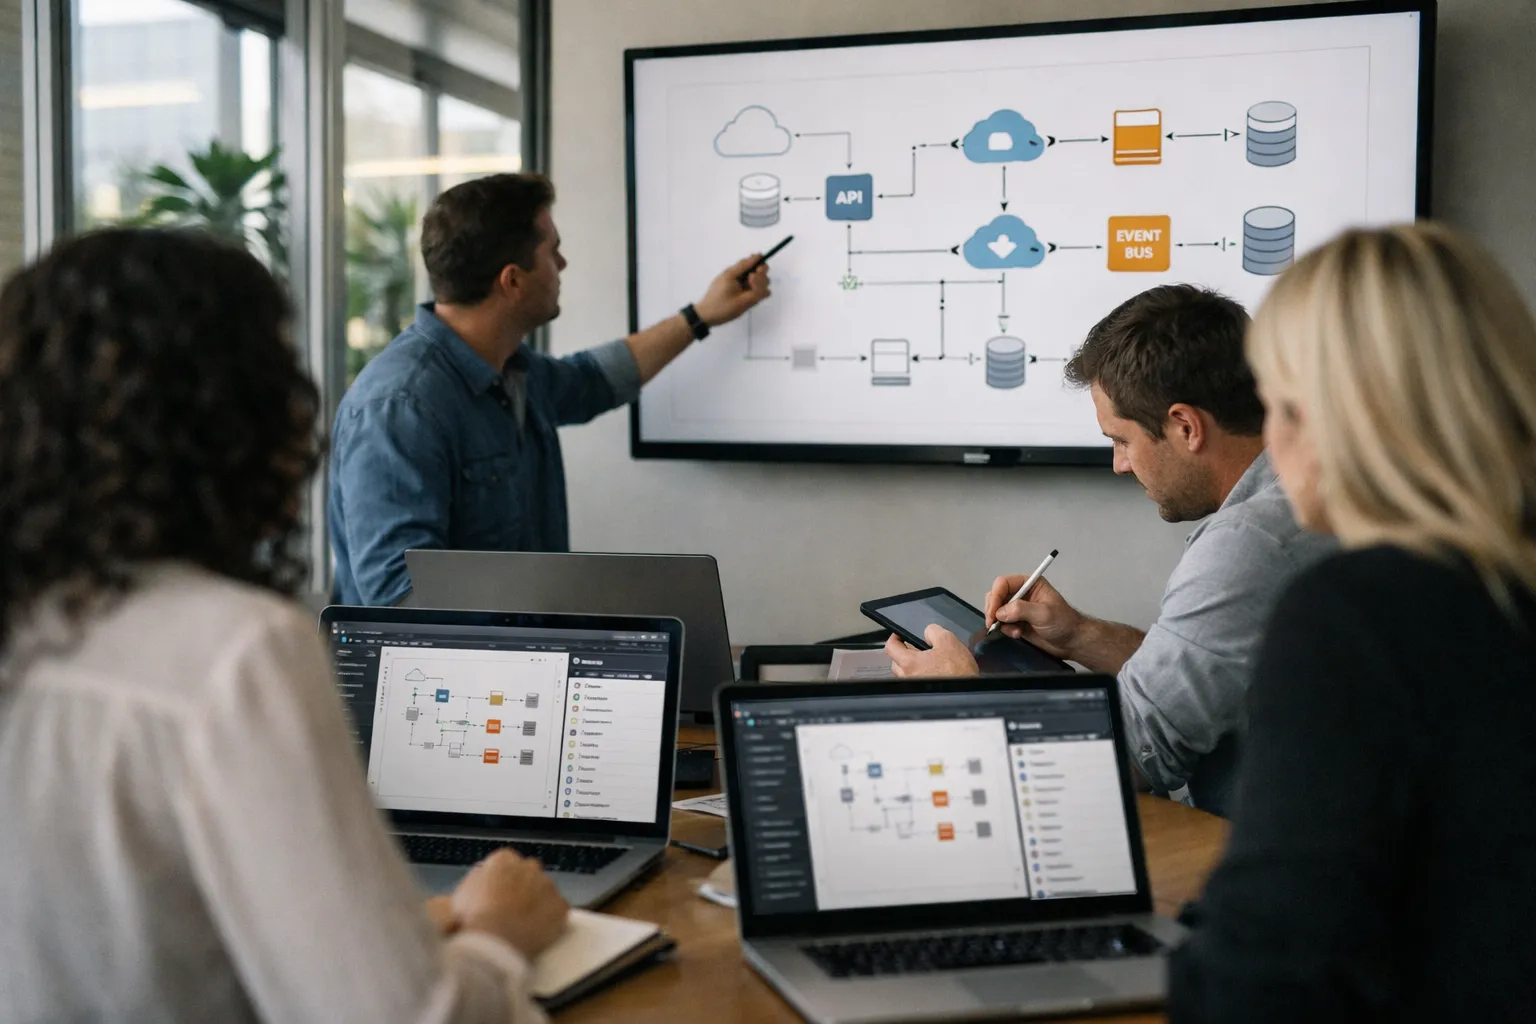
Overview: Low-code platforms are no longer an experimental procurement line item — by August 2026 they are a standardized element of enterprise application strategies. This update examines what has changed since early productizations: larger vendor investments in AI-assisted development, stronger observability and exportability guarantees, evolving cost models, and sharper regulatory scrutiny (especially around embedded AI). For enterprise architects and procurement leaders, the central questions remain the same—can low-code meet enterprise-grade scalability, integration needs and long-term ROI? This article synthesizes recent patterns, vendor behaviors, and practical steps to evaluate low-code as a strategic component of your application portfolio.
Background: what shifted through 2024–2026
Three developments between 2024 and mid‑2026 have reshaped the low-code calculus:
- AI-assisted development: Major platform vendors embedded large language model (LLM) and code-generation assistants into design and testing workflows. Microsoft’s Copilot expansion into Power Platform in 2023 presaged broader LLM integration across the market, accelerating citizen-developer productivity while introducing model-risk considerations.
- Operational maturity: Customers demanded enterprise-grade telemetry and exportability. OpenTelemetry has become the de-facto tracing approach for many vendors, and better source-control and CI/CD exports are now baseline features rather than premium add-ons.
- Price model complexity: Consumption-based and per-interaction pricing has proliferated. Vendors that initially promoted per-developer licensing added per-runtime, per-API-call or per-LLM-inference charges, complicating TCO forecasting.
Data & evidence: observable 2026 trends and vendor behavior
Observable, verifiable market behaviors and product features as of August 2026:
- Most leading low-code vendors (platform-first and integration-first) now provide built-in connectors for popular cloud message brokers (Kafka, AWS EventBridge, Google Pub/Sub) and support event-driven architectures as first-class citizens.
- OpenTelemetry support and trace export are widely advertised in vendor documentation; procurement teams increasingly require OpenTelemetry compatibility in RFPs to integrate with existing observability backplanes.
- LLM integrations are common: platforms ship connectors to major model providers and offer in-editor prompt assistance, but they also require buyers to evaluate data exfiltration risk, model hallucination and inference costs.
- Vendor pricing moved toward mixed models: base subscriptions plus consumption charges (runtime units, API calls, connector throughput, LLM tokens). Procurement organizations report that predictable TCO now requires representative production load tests beyond standard performance reports.
Multiple perspectives: vendor archetypes and how they've evolved
1) Platform-first suites (cloud & ERP vendors)
How they’ve changed: these vendors tightened integration with their cloud services, providing strong single‑pane operational models and native SLAs. They increasingly embed managed AI services and offer tenant-aware orchestration across identity, data and analytics. Trade-offs remain: good fit when you anchor most of your stack to the same vendor, but higher risk of lock-in if you need cross-cloud portability.
2) Integration-first low-code
How they’ve changed: integration-first offerings improved connector depth (including richer error semantics, retry strategies, and transactional compensations) and added features for composing serverless functions and external microservices. Buyers gain flexibility but shoulder more responsibility for governance, telemetry consolidation and end-to-end performance.
Scalability & engineering patterns that work in 2026
Scalability remains the decisive factor. Updated patterns and guardrails to apply now:
Compute and concurrency
- Continue to offload CPU‑intensive or highly concurrent work to serverless or dedicated microservices; now explicitly include capacity and cold-start testing for integrated serverless functions as part of platform POCs.
- Favor event-driven ingestion pipelines for high throughput; low-code components should handle orchestration and UX state while stateless services perform heavy lifting.
- Validate platform autoscaling at a topology level (runtime + downstream services + connectors), not just the low-code runtime alone.
Data, multi-tenancy and sovereignty
- Demand explicit datastore exportability and ownership clauses. Do not assume platform datastores are the canonical source for regulated records—define canonical stores in enterprise databases.
- Confirm encryption-at-rest, key management (BYOK), and data residency options. New regulations and internal policies increasingly require regional isolation for AI inference and data used in prompts.
Observability and operability
- Require OpenTelemetry-compatible tracing and log export in procurement; insist on trace context propagation across connectors and serverless invocations.
- Include performance SLIs for end-to-end scenarios that cross the low-code layer and backend services; validate with chaos and capacity tests before production rollout.
Integration: connectors, API contracts and LLM risks
Integration quality is a differentiator. 2026-specific considerations:
- Connector quality: evaluate not just the presence of a connector but its transactional behavior, idempotency guarantees, error mappings, and backpressure handling under load.
- API-first and contract-driven approaches are essential: treat low-code workflows as consumers and producers of well-defined APIs with versioning and contract tests.
- LLM usage: if you embed LLMs for UX generation, code suggestions, or business logic, implement model-risk controls—prompt logging, PII scrubbing, human-in-the-loop gates, and cost caps for inference traffic.
ROI reality in 2026: new levers and new risks
Short-term wins—faster delivery, lower upfront build cost and wider participation—still hold. But new recurring costs and governance overheads must be baked into ROI models:
- Initial development savings remain potent for forms, approval flows and intra-organization apps.
- Licensing and consumption costs now often include per-runtime and per-LLM charges; simulate probable production loads when modeling 3–5 year TCO.
- Operational costs shifted up: telemetry integration, connector maintenance, and model-risk governance require staff time and tooling.
- Technical debt: platforms that do not export artifacts or generate reproducible infrastructure code increase reimplementation risk if you need to migrate.
Practical approach: maintain a suitability matrix that includes AI exposure, transaction volume, compliance risk and expected lifecycle length. Use low-code for short-to-medium life-cycle, compositional or UX orchestration roles; use traditional development for high-throughput, stateful, or long-lived core services.
Updated implementation playbook: governance, CoE and platform engineering
- Transform CoEs into platform engineering teams responsible for templates, reusable components, cost monitoring, model governance and SRE playbooks.
- Mandate Git‑backed artifacts and automated CI/CD pipelines; adopt GitOps patterns where platform artifacts are stored as versioned, auditable code.
- Apply policy-as-code (OPA, Rego) to enforce connector usage, data residency, and runtime rules at deploy time.
- Test LLM integrations with dedicated MRM (Model Risk Management) playbooks: prompt-logging, adversarial tests and human reviews.
- Run realistic capacity and chaos tests that include downstream systems, connectors and third-party rate limits rather than only platform synthetic tests.
Procurement and evaluation checklist — 2026 edition
- Integration: depth of connectors, transactional behavior, rate-limit handling, and event-stream first-class support.
- Scalability: end-to-end throughput baselines, multi-region deployments, and documented behavior under connector saturation.
- Observability: OpenTelemetry support, trace propagation across external calls, and export formats compatible with your observability stack.
- Data & AI: datastore exportability, BYOK support, data residency controls, and explicit model-risk features (prompt logging, PII filters, inference cost controls).
- Cost model: representative consumption scenarios, LLM inference pricing, and cost-alerting tooling; insist on bill-predictability guarantees where possible.
- Governance & extensibility: Git-backed artifacts, CI/CD integration, policy-as-code hooks, and support for serverless/custom code embedding.
Implications for enterprise teams
Low-code can significantly reduce delivery friction if adopted with rigorous architecture and procurement hygiene. The new 2026 risks—LLM exposure, consumption-based inflation, and supply-chain concerns around third-party connectors—mean enterprise teams must treat low-code platforms as first-class components in their security, observability, and legal frameworks. When CoE, procurement and platform engineering align, low-code becomes an accelerant for digital initiatives; when it is used as a shortcut without controls, it creates hidden costs and governance gaps.
Outlook: what to watch for next 12–18 months
Near-term drivers to monitor:
- Standardization of AI governance features in platforms (audit trails, model certification badges).
- Greater pressure from CIOs for exportability guarantees—vendors will compete on “escape hatch” features that allow migration or on-prem exports.
- Consolidation in the vendor space: expect continued M&A as hyperscalers and ERP vendors integrate popular integration-first features.
FAQ: Common procurement and architecture questions
How should I evaluate a low-code vendor’s AI features?
Require transparency on model providers, prompt handling, data retention, and PII protections. Include model-risk-specific acceptance tests in your POC: prompt redaction, hallucination rate under domain prompts and inference-cost estimates under projected loads.
Can low-code be used for high-throughput transactional systems?
Generally, treat low-code as an orchestration and UX layer. High-throughput transaction processing is better implemented in independently scalable services; validate patterns where low-code invokes serverless functions or microservices that handle the transactional load.
What’s the best way to control runaway costs from consumption pricing?
Simulate realistic production traffic during procurement, set hard cost caps and alerts, and use throttles at gateway/connector layers. Track per-feature cost attribution and require vendors to expose consumption metrics via APIs.
How do I ensure observability across low-code and legacy systems?
Insist on OpenTelemetry-compatible tracing and end-to-end trace context propagation. Run scenario-based SLI tests that exercise cross-system flows and include traces, metrics and logs in your runbook escalation paths.
What governance structure works best?
A central platform engineering team (evolved CoE) that owns templates, policy-as-code, CI/CD pipelines, and model governance. Decentralized teams can build on approved components under this guardrail to preserve speed without sacrificing control.