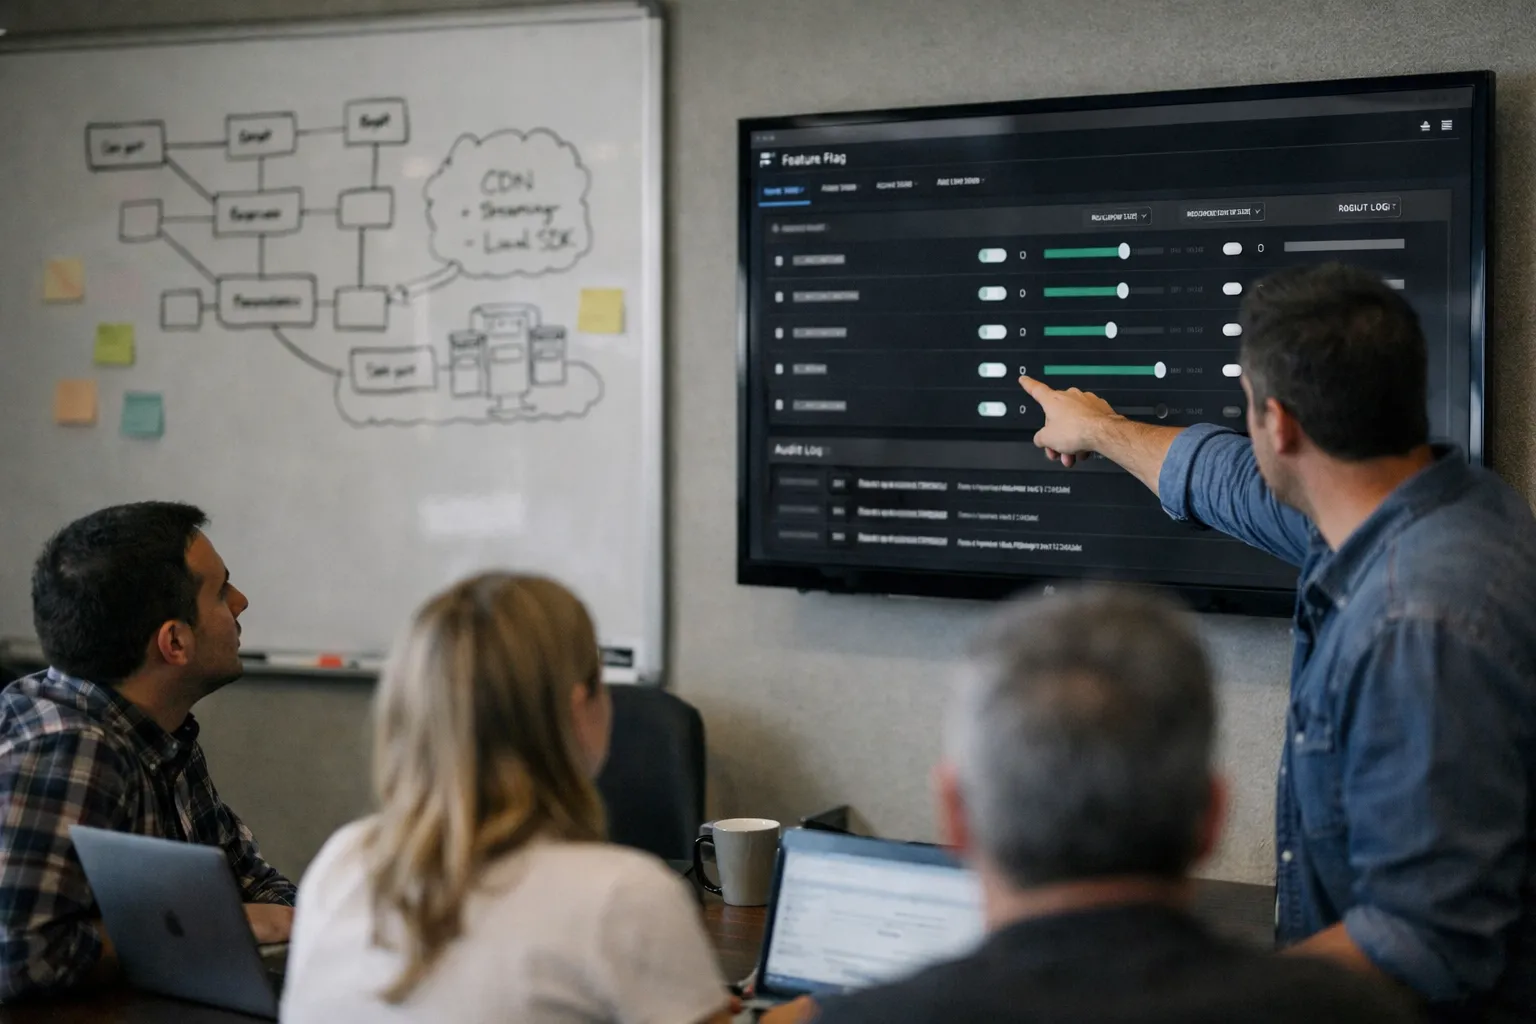
Feature flags remain one of the most powerful levers enterprises use to decouple deployments from releases. Since this guide first ran in early 2026, the practice has continued to mature: edge/WebAssembly evaluation is now operational in production at scale, policy-as-code is a platform expectation, and teams are paying closer attention to telemetry costs and privacy. This refreshed August 2026 guide walks platform engineers, SREs and engineering managers through an actionable implementation plan for microservice environments: updated architecture trade-offs, necessary integrations, governance templates, rollout patterns and how to measure ROI today.
Quick note from me — I learned discipline in the kitchen by labeling jars and throwing out anything with a missing date. The same discipline saves engineering teams from "flag soup." This guide gives you the labels, the recipes and the timing for a reliable rollout.
Who this is for and why it matters
This guide is for platform engineers, SREs, release engineering leads and engineering managers at mid‑to‑large enterprises running polyglot microservices, serverless or edge functions. You’ll get:
- Practical architecture choices (server, client, Wasm/edge, hybrid)
- An integration checklist that reflects 2026 toolchains
- A phased 90‑day pilot plan you can run next week
- Governance templates and telemetry guidance tuned for cost and compliance
Why this matters now: teams that treat flags as product controls reduce blast radius, accelerate experimentation, and provide auditable release artifacts. In 2026 the bar for audit, privacy and edge consistency is higher — the platform decisions you make today determine whether flags are a safety net or a future liability.
Prerequisites & context
Before you start, inventory release processes, telemetry costs and regulatory constraints. At minimum be able to answer:
- How many deploys per service per week are you doing now?
- Which services handle regulated data, payments, or cross‑border flows?
- Where are your latency budgets tightest (edge, API, batch)?
- What observability and data platforms are in use (OpenTelemetry, Prometheus, Datadog, Snowflake/BigQuery)? What are acceptable retention and sampling levels?
Minimum technical prerequisites for a successful pilot:
- A service integrated with a feature‑flag SDK or a Wasm evaluation host, instrumented for traces & metrics
- CI/CD access to implement GitOps-style flag lifecycle (flag-as-code)
- RBAC wired to your identity provider (SAML/OIDC/SCIM)
Step 1 — Define business use cases and measurable outcomes
- Prioritize high‑value use cases. Typical 2026 priorities: emergency kill switches for critical flows (payments, auth), progressive canaries for high‑traffic services, dark launches for backend features, and personalization at the edge for global latency-sensitive surfaces.
- Attach specific metrics to each use case. Examples: rollback incidents avoided, MTTR when toggling a flag vs redeploy, time‑to‑significance for experiments, evaluation latency cost and per‑flag telemetry spend. For emergency flags, define a target time-to‑revoke (goal: seconds to minutes).
- Set guardrail thresholds. For canaries and experiments define absolute safety thresholds (error‑rate delta, latency SLO breaches) that trigger automated rollback or escalation. Make these machine-enforceable where feasible.
Why this matters: flags without measurable outcomes become clutter. Tie flags to product and operational KPIs before they are created — don’t skip this governance step.
Step 2 — Choose an architecture: server, client, edge (Wasm) or hybrid
Architecture remains the most consequential decision. In August 2026, these trade-offs are clearer because several teams now run Wasm evaluation at global scale and vendors offer attested runtimes.
- Server‑side evaluation — centralized evaluation (control plane + evaluation gateways) remains the safest default for safety‑critical decisions (payments, entitlement). Pros: audit context, easier secrets protection. Cons: added latency and scaling cost.
- Client‑side evaluation — browser or mobile SDKs are best for UI personalization where local latency matters. Never use client-only evaluation for secrets or safety‑critical logic.
- Edge / Wasm evaluation — evaluating flags in Wasm runtimes (Cloudflare Workers, Fastly Compute, or self-hosted Wasm on k8s) now matches client latency with stronger control than browser SDKs. Best practices: sign and attest Wasm modules, restrict which flags are evaluated at the edge, and run periodic reconciliation against the control plane to detect drift.
- Hybrid — recommended for most enterprises: server-side for safety-critical logic and attested edge evaluation for personalization and global rollouts.
Key design decisions to document:
- Deterministic bucketing algorithm across languages (pin algorithm version in metadata; prefer shared libraries or OpenFeature-compatible approaches)
- Distribution method (streaming websocket/SSE, delta CDN bundles, message bus like Kafka/Pulsar, or signed artifact distribution for Wasm binaries)
- Fallback semantics for timeouts or degraded connectivity (define defaults per flag risk class)
Step 3 — Integration checklist (must-haves for August 2026)
Feature flag platforms are now expected to integrate deeply with delivery and governance tooling:
- CI/CD & GitOps: store flag definitions in repo (YAML/JSON), tie flag lifecycle to PRs, and auto‑reconcile environments. Example: a PR that adds an API route also includes the flag definition and metadata; merge triggers the reconciler.
- Identity & RBAC: enforce SAML/OIDC + SCIM provisioning. Separate roles for flag author, approver and deployer. Require multi‑person approvals for high‑impact toggles.
- Observability: send evaluation events and flag context to OpenTelemetry traces and metrics. Tag traces with flag ids and variant values to speed triage and attribution.
- Analytics & data platform: stream evaluation and event data to your warehouse (Snowflake/BigQuery) and to A/B platforms. Use consistent join keys and consider sampling strategies to control egress and storage cost.
- Policy‑as‑code: integrate OPA/Rego (or equivalent) checks in CI to validate naming, ownership and risk classification before merge.
- Secrets & compliance: ensure flags that gate sensitive ops require server‑side evaluation, or tie to a secure enclave (e.g., Nitro, SEV, SGX) or attested Wasm runtime.
- AI‑assisted signals: many platforms now provide ML‑driven anomaly detection on flag rollouts — integrate these signals into incident channels but maintain human oversight for final decisions.
Step 4 — Governance, naming, lifecycle and security
Governance is table stakes. Update your policies for 2026 realities:
- Naming & taxonomy: enforce a structured schema such as org.team.service.capability.env.version.action. Example: enterprise.payments.billing.autorenew.prod.v2.enable. Reject non‑compliant names in CI.
- Ownership metadata: require owner, business justification, launch date, expiry date and risk classification on creation.
- Lifecycle automation: flags should auto‑transition: experimental → standard → deprecated. Create automated reviews for flags older than your TTL (90 days is common for experiments).
- RBAC & approvals: split creation from production-enablement privileges and require two‑person approval for payment/PII flags.
- Auditability & retention: keep immutable logs of flag changes and evaluation events for compliance retention windows. Use append‑only storage or WORM when required.
- Security: never gate secrets or cryptographic operations via client‑only flags. Use server-side evaluation or protected enclaves; require signed references for Wasm modules and remote attestation where allowed.
Step 5 — Scalability & operational patterns
As evaluation moves closer to the edge, operational patterns evolve:
- Delta bundles + CDN: ship small delta updates for SDK and Wasm bootstraps through CDNs to reduce bandwidth and speed cold starts.
- Streaming for immediate changes: use reliable streaming (SSE/HTTP2/WebSocket) or a message bus (Kafka, Pulsar) for near-instant propagation of emergency toggles.
- Local caches & eventual consistency: prefer local evaluation with deterministic refresh windows; design sensible defaults and degrade gracefully.
- Rate limiting & back‑pressure: protect central endpoints; embed SDK-side throttling and circuit breakers to avoid cascading failures.
- Telemetry cost control: sample high-volume evaluation events (1–5%) while fully logging safety‑critical evaluations. Use aggregated counters and periodic full snapshots for analytics.
- Chaos‑testing rollbacks: automate drills where a high‑impact flag is toggled; measure MTTR and refine playbooks.
Step 6 — 90‑day implementation plan (updated for August 2026)
- Days 0–14 — Discovery & scoping:
- Select 3 pilot use cases: one safety‑critical (payments/auth), one experiment, one edge personalization.
- Map dependencies (data, identity, CI). Identify telemetry destinations and sample plans to control cost.
- Secure an exec sponsor and SRE sign‑off for emergency workflows.
- Days 15–30 — PoC & instrumentation:
- Install SDKs in one core service and deploy a Wasm module to an edge host (or CDN testbed).
- Emit evaluation events via OpenTelemetry; export to tracing and a sampled analytics stream.
- Run load and latency tests to quantify evaluation cost and CDN caching behavior.
- Days 31–60 — Expand & harden:
- Roll SDKs to a small fleet (10–20 services) and enable GitOps workflows for flag definitions.
- Add RBAC, policy‑as‑code checks in CI and immutable audit logging.
- Define and test emergency rollback runbooks and a quarterly kill‑switch drill.
- Days 61–90 — Enterprise adoption:
- Publish naming, metadata and lifecycle standards; run training sessions and office‑hours for teams.
- Automate stale‑flag reviews and integrate flag telemetry into weekly platform KPIs.
- Start decommissioning brittle release gates and report ROI metrics to stakeholders.
At each stage capture numbers: rollout latency, evaluation QPS, flag churn rate, rollback incidents avoided, telemetry spend, and developer time saved. These form the basis of your ROI and capacity planning.
Step 7 — Measuring ROI and building the business case
Quantify cost avoidance and value uplift:
- Incident cost avoidance: measure incident‑hours avoided by toggling flags versus full rollbacks and multiply by loaded hourly rates.
- Experiment revenue lift: attribute uplift from experiments to cohort size and ARPU and report incremental revenue from successful experiments.
- Developer efficiency: estimate hours saved from fewer long‑lived branches and quicker rollouts (use time‑tracking or pulse surveys for accuracy).
- Platform cost: include vendor licensing, hosting, governance implementation and ongoing SRE operations.
Present a three‑line ROI model: annualized incident avoidance + experiment uplift + developer time saved − platform cost = Net ROI. Be conservative on uplift assumptions and document sensitivity ranges.
Common mistakes and how to avoid them
- Flag sprawl: automate TTLs and stale‑flag tickets. Treat flags as code, not permanent config.
- Poor naming and missing ownership: enforce naming in CI and require owner & business justification on create.
- Insufficient telemetry or over‑logging: include flag context in traces and apply sampling for volume control—without it, experiments and incidents are blind or prohibitively expensive.
- Security gaps: avoid client‑only evaluation for safety‑critical logic; require server evaluation or attested edge where necessary.
- Not testing at scale: POCs often under‑provision evaluation endpoints—run production‑scale tests before enterprise rollout.
Pro tips (practical, field tested)
- Don’t skip audit context: when creating a flag include a short business justification and link to the PR/epic — future you will thank you in incident reviews.
- Pin your bucketing algorithm: store algorithm and seed in flag metadata and reject changes without a coordinated re‑bucketing plan.
- Automate stale‑flag tickets: implement a scheduled job that creates review tickets for flags approaching expiry as a platform SLO.
- Practice emergency rollbacks: run quarterly "kill‑switch" drills and measure MTTR end‑to‑end, including approval and observability validation.
- Manage telemetry spend: sample high‑volume flags (1–5%) and retain full logs only for safety‑critical flags or for short retention windows required for compliance.
- Edge consistency: when using Wasm include reconciliation checks and require signed/attested artifacts to avoid drift and supply‑chain risk.
Example: naming and lifecycle policy (template)
Adopt a small, enforceable scheme:
- Name: org.team.service.capability.env.version.action
Example: enterprise.payments.billing.autorenew.prod.v2.enable - Mandatory metadata: owner, business justification, launch date, expiry date, risk profile, linked PR/issue
- Lifecycle: experimental → standard (after defined thresholds) → deprecated → removed (automated 90‑day review ticket)
When to build vs buy in 2026
Build if you need strict on‑prem determinism, bespoke evaluation connected to proprietary hardware, or data residency constraints a vendor cannot meet. Buy (managed or hybrid) if you want faster time‑to‑value, built‑in RBAC/audit and vendor scaling. A common 2026 pattern: managed control plane + self‑hosted evaluation gateways and attested Wasm modules to balance performance and compliance.
Final recommendations
Treat feature flags as a platform capability, not a developer convenience. Prioritize:
- Clear business use cases with KPIs
- Architecture that balances latency, governance and edge requirements
- Deep integrations with CI/CD, identity, observability and analytics
- Policy-driven governance (naming, lifecycle, RBAC, immutable audits)
- Scale testing, telemetry cost control and a phased 90‑day rollout
Get these right and feature flags will reduce blast radius, speed learning and become an auditable linchpin of your delivery platform.
Common questions
How many flags is too many?
There’s no universal number. Proliferation becomes a problem when flags lack owners, metadata or expiry dates. Track "flag churn" (create vs delete) and enforce TTLs (commonly 60–90 days for experimental flags). If a flag’s owner and purpose can’t be explained in 60 seconds, it should be reviewed or removed.
Can I safely evaluate flags at the edge (Wasm)?
Yes — when you apply controls. Use signed Wasm artifacts, runtime attestation where available, restrict which flags are evaluated at the edge (no secrets or financial grants), and run reconciliation jobs to detect drift. Combine edge evaluation for latency‑sensitive personalization with server checks for safety‑critical decisions.
How do I keep telemetry costs manageable?
Classify flags by risk and volume. Fully log safety‑critical evaluations; sample high‑volume personalization flags (1–5%). Use aggregated metrics for most operational dashboards and occasional full snapshots for analytics or experiment validation. Monitor egress and storage spend in your data platform and include it in the ROI model.
What policies should I automate first?
Start with naming enforcement, mandatory metadata (owner, expiry), and stale‑flag ticketing. Next add RBAC checks and approval workflows for high‑risk environments. Policy‑as‑code (OPA/Rego) in CI makes these checks reproducible and auditable.
How do I measure success in the first 90 days?
Track adoption and impact: number of services with SDKs/Wasm, flag churn rate, rollback incidents avoided, MTTR for critical incidents, time‑to‑significance for experiments, and developer hours saved. Report these weekly and iterate on the pilot.