Overview
Enterprises choosing an event-driven backbone in mid‑2026 face a more nuanced landscape than in 2024–2025. Managed Kafka offerings (Confluent Cloud, Redpanda Cloud, Amazon MSK) have matured with KRaft, tiered storage and serverless consumption models; event mesh vendors (Solace PubSub+, vendor-neutral fabrics, and expanded cloud-native mesh patterns) have added richer protocol translation, centralized policy engines and cost‑aware routing. This update revisits the core tradeoffs—scalability, integration surface, operations and ROI—and gives an up‑to‑date decision framework and pilot checklist for architects evaluating hybrid deployments today.
Background: what changed since March 2026
Key shifts through H1 2026 that matter to architects:
- KRaft is mainstream in managed Kafka: Major managed Kafka services have moved off Zookeeper to KRaft-based control planes, simplifying cluster operations and lowering broker maintenance windows.
- Tiered/remote storage is default: Many providers now offer transparent tiered storage or object-store-backed retention, reducing hot‑storage costs for long tails of data.
- Cloud vendors adopted mesh patterns: AWS, Azure and Google have expanded event-bus features and native connectors that mimic mesh behaviours—cross-account/tenant routing and finer policy controls—reducing the need for third‑party gateways in some scenarios.
- Standards and observability converged: Broader CloudEvents adoption, improved OpenTelemetry integrations and vendor tools for end‑to‑end tracing have made cross‑platform SLOs and debugging easier.
- Cost scrutiny intensified: Rising cloud egress and storage pressure pushed teams to re‑examine cross‑region replication patterns; intelligent routing in meshes became a clear lever to reduce charges.
Data and evidence: current signals to weigh
Industry signals through 2025–26 show three durable trends:
- Hybrid architectures dominate: Most large organizations run mixed topologies—centralized high‑throughput streaming in managed Kafka, with meshes or protocol bridges for edge and SaaS connectivity.
- Developer productivity matters as much as raw throughput: Teams increasingly measure integration time (hours to onboard a SaaS/webhook/device) and mean time to recover (MTTR) as primary ROI drivers.
- Policy‑driven governance is a procurement filter: Security and compliance teams require end‑to‑end dataflow modeling and policy enforcement; solutions that provide centralized policy and visibility score higher in evaluations.
Concrete metrics you should capture in a pilot (updated priorities for 2026):
- Latency percentiles (p50, p95, p99) end‑to‑end and per hop
- Cost per million events ingested and delivered (including egress/replication)
- Developer time to integrate a new endpoint (hours/days)
- Operational incidents per quarter and mean time to repair (MTTR)
- Policy enforcement coverage: percent of event flows covered by centralized governance
Core technical differences (refreshed)
Model and semantics
- Managed Kafka: Still topic/partition oriented with strong support for stateful stream processing and event sourcing. KRaft adoption reduced control-plane complexity and improved scaling predictability for many managed offerings.
- Event Mesh: Fabric or broker federation that emphasizes flexible delivery semantics (push/pull, request/reply), content‑based routing and protocol translation. Meshes now routinely surface policy controls and transformation pipelines as first‑class features.
Scalability and cost behavior
Two practical points for 2026:
- Throughput scaling: Kafka’s partition model remains the predictable choice for linearizing throughput; managed services now offer autoscaling for brokers and consumers, but partition management and rebalancing still require architectural discipline.
- Cross‑region costs: Event meshes’ routing intelligence reduces unnecessary replication and egress, which matters as cloud providers increase egress and inter‑region charges. For multi‑region command/control or IoT fleets, meshes can materially reduce billed traffic.
Integration surface
Today’s integration calculus favors meshes in highly heterogeneous environments and Kafka in analytics‑heavy pipelines:
- Managed Kafka: Large connector ecosystems (Kafka Connect, Debezium) and mature stream processing frameworks (ksqlDB, Flink) make it efficient for analytics, CDC and stateful processing.
- Event Mesh: Built‑in protocol bridges (AMQP, MQTT, JMS, HTTP, WebSockets), transformation and schema routing reduce custom adapter work—especially when integrating legacy middleware, SaaS webhooks or constrained edge devices.
Operational and implementation tradeoffs (updated)
Operations today
Managed Kafka removes much low‑level broker work, but teams still own the application layer: partition layouts, consumer partitioning logic, connector health and stream processing tuning. Event meshes shift work from application code to the mesh control plane—reducing per‑service glue but concentrating requirements on mesh operators to maintain routing policies, protocol adapters and cross‑domain security.
Observability and governance
OpenTelemetry and CloudEvents adoption have improved cross‑platform tracing; still, unified governance requires deliberate modeling:
- Use a schema-first approach (schema registries or schema discovery) to enforce compatibility across both Kafka topics and mesh‑routed events.
- Define SLOs for message delivery and retention and measure them with distributed traces that include mesh hops and Kafka consumer lag.
Updated decision framework: practical checklist for June 2026
- Primary workload: High‑throughput analytics and stateful stream processing → managed Kafka core.
- Heterogeneous endpoints: Many protocols, legacy systems, or global edge fleets → event mesh or two‑layer hybrid.
- Multi‑region and cost sensitivity: If egress replication costs and selective routing matter, favor a mesh for edge aggregation and selective replication.
- Governance and regulatory needs: If centralized policy enforcement (masking, retention rules, routing policies) across heterogeneous protocols is critical, meshes reduce cross‑team coordination costs.
- Operational model and skills: If you have a strong streaming platform team, Kafka gives greater control and throughput efficiency; if you want to minimize application integration code, a mesh reduces developer burden.
Common hybrid patterns (2026 examples)
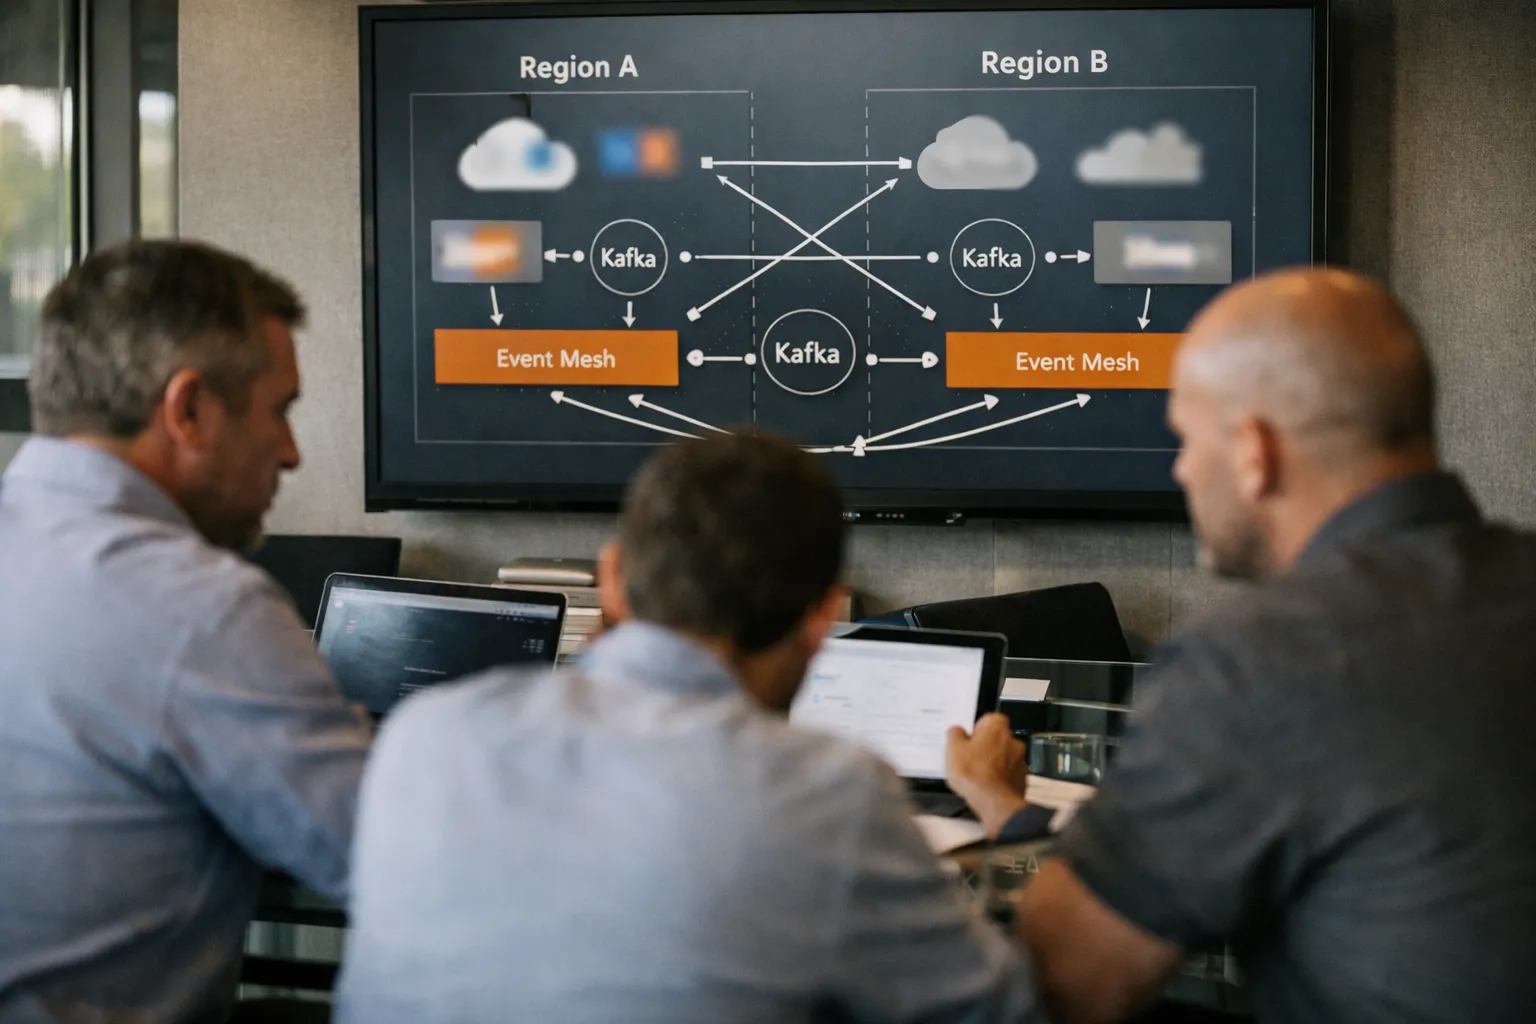
- Kafka core + mesh edge: Managed Kafka as the analytics and durable core; an event mesh handles SaaS integrations, device gateways and cross‑region selective routing.
- Strangler approach: Start with a mesh to decouple domains and onboard endpoints quickly; migrate heavy stream processing out of the mesh into a Kafka core when stateful processing or long‑term retention is needed.
- Two‑layer mesh federation: Multiple meshes federated across organizational boundaries with a central Kafka analytics plane for cross‑domain aggregation and ML/BI workloads.
Updated pilot plan: what to measure and how
Run a two‑phase pilot with clear SLOs and economic metrics:
- Functional pilot (2–6 weeks): Implement one business flow end‑to‑end with both approaches. Measure integration developer hours, number of adapters, and first‑call resolution for incidents.
- Scale and resilience test (2–8 weeks): Replay production peaks and cross‑region failovers. Measure p50/p95/p99 latencies, consumer lag, retention costs, and cross‑region egress spend.
Translate results to business terms: feature delivery cadence (weeks per release), compliance coverage (percent of flows with policy enforcement), and 12–36 month TCO (platform fees + operational FTE + integration engineering costs).
Multiple perspectives: what vendors, architects and analysts emphasize
- Vendors: Managed Kafka vendors sell control and throughput efficiency; mesh vendors sell reduced integration work and centralized policy. Many vendors now market hybrid integrations to capture both value propositions.
- Platform engineers: Prefer Kafka for predictable throughput and fine‑grained stream processing control; ask for better tooling around partition management and consumer scaling.
- Integration teams: Prefer meshes for rapid onboarding of heterogeneous endpoints and for reducing custom adapter maintenance.
- Security/compliance: Favor solutions that provide end‑to‑end dataflow modeling and centralized enforcement; meshes often simplify cross‑domain policies while Kafka registries and ACLs provide per‑topic controls for stricter processing scenarios.
Implications for enterprise architects
Practical implications for decisions made in mid‑2026:
- Expect hybrid architectures to be the norm—not an exception. Design for clear ingress/egress boundaries, schema contracts and observability across both layers.
- Measure integration velocity as a primary ROI lever. Faster onboarding of endpoints can trump modest per‑message cost increases if it accelerates time‑to‑market.
- Watch egress and cross‑region cost exposure; use selective replication and routing policies to reduce cloud bills.
- Adopt CloudEvents and OpenTelemetry as interoperability pillars to minimize vendor lock‑in and simplify tracing across mesh and Kafka domains.
Outlook: what to watch through 2026–2027
- Further convergence: Expect more vendor features that blur the line—Kafka vendors adding gateway/mesh capabilities and mesh vendors improving stream processing integrations.
- Standardization momentum: Wider CloudEvents and schema governance adoption will lower integration friction.
- Cost transparency: Tools that map event flows to cost centers and compliance posture will become procurement must‑haves.
Conclusion
There is still no single winner. Managed Kafka remains the pragmatic core for throughput‑intensive, stateful processing; event meshes deliver faster, lower‑friction integration and cost‑aware routing for heterogeneous, multi‑region environments. In 2026 the best practice for most large enterprises is hybrid: a managed Kafka core for analytics and durable streaming, augmented by an event mesh for edge, SaaS and cross‑domain orchestration. The decisive factor is measurement—run representative pilots, capture developer productivity and end‑to‑end costs, and let SLOs and business outcomes drive the final architecture.
FAQs
Should I replace my on‑prem Kafka with a managed Kafka or an event mesh?
Not necessarily. Many organizations adopt a staged approach: move analytics and heavy stream processing to a managed Kafka to reduce ops, and add an event mesh for edge and cross‑domain integrations. Base the choice on workload type, operational skills and cost sensitivity—validate with a pilot.
How should I handle schema and compatibility across mesh and Kafka?
Use a schema‑first strategy: enforce schemas via a registry (or discovery) and adopt a canonical event format such as CloudEvents for metadata. Implement compatibility checks in CI pipelines and automate schema validation before deployment to prevent runtime incompatibilities.
What observability should be in place before a production rollout?
Instrument the entire path with OpenTelemetry traces and metrics: producer latencies, broker/pod health, consumer lag, mesh routing latencies, and end‑to‑end SLO dashboards (p50/p95/p99). Also track integration churn (adapter failures and maintenance hours) as an operational KPI.
Can a mesh reduce my cloud egress bill?
Yes—meshes that perform intelligent, content‑based routing and local aggregation can reduce cross‑region replication and egress. Quantify this in a scale pilot by measuring inter‑region traffic patterns and modeled egress charges.
How long should a pilot run to be credible?
Run a two‑phase pilot: a 2–6 week functional pilot for integration velocity and a 2–8 week scale test that replays peak traffic and failovers. Ensure the pilot exercises cross‑region patterns, security policies, and failure modes you expect in production.