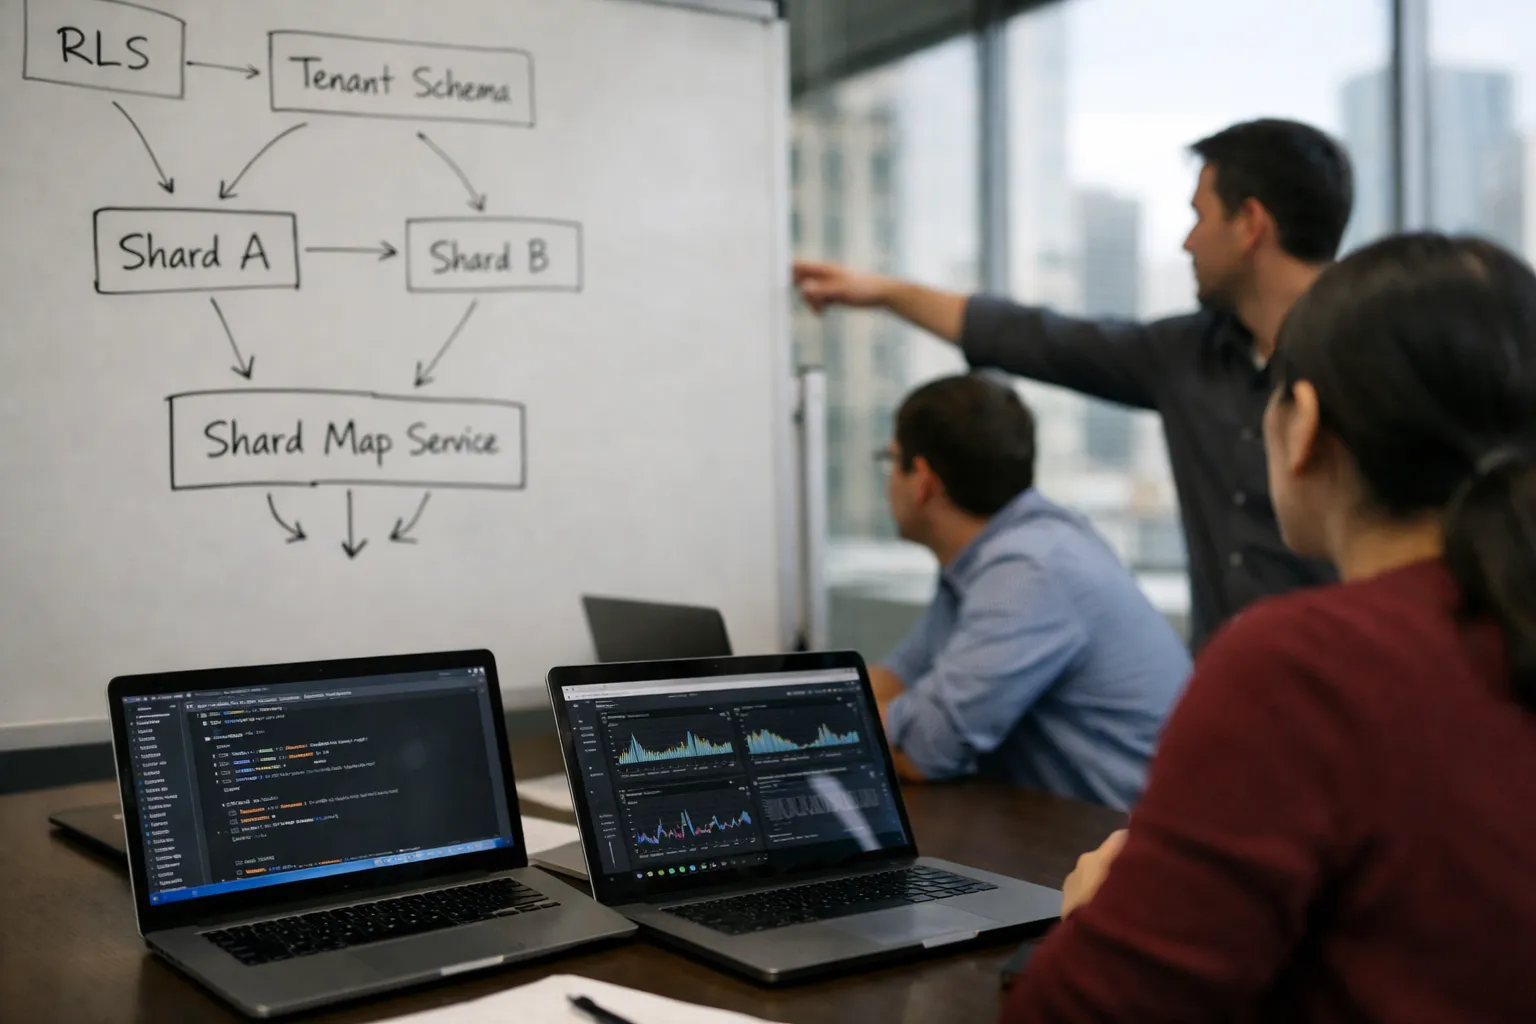
Enterprises building or operating multi-tenant SaaS platforms face a recurring set of technical and business constraints: strong isolation for compliance, predictable scalability, simple integration with downstream systems, and a demonstrable ROI on infrastructure choices. This guide walks architects and engineering leaders through a practical decision and implementation path for multi-tenant data isolation using three commonly used patterns—Row‑Level Security (RLS), tenant-dedicated schemas, and sharded databases—plus hybrid mixes. It focuses on implementable steps, migration strategies, and the operational controls needed for enterprise solutions in 2026.
Why tenant isolation matters for enterprise solutions
Isolation is not purely a security checkbox. It affects performance, compliance, operability and total cost of ownership (TCO). Key drivers for revisiting or implementing a new isolation strategy include:
- Regulatory and data residency requirements that require tenant-specific controls.
- Performance variability from noisy tenants that impacts SLAs for others.
- Integration needs—enterprise customers often require direct BI access, ETL hooks, or backups.
- Scalability targets: expected growth in number of tenants and per-tenant data volume.
- Operational overhead: backup/restore, tenant offboarding, and debugging.
Patterns overview: RLS, schemas, shards
Each pattern has trade-offs in isolation strength, operational complexity, cost, and integration effort. Use the following decision axes: tenant size (metadata+data volume), performance variability, compliance sensitivity, and integration needs.
Row‑Level Security (RLS)
RLS enforces tenant access within a shared table by filtering rows at the database level (Postgres, for example, supports RLS policies). Advantages: low infrastructure cost, easy schema evolution, simple reporting across tenants. Limitations: potential noisy-neighbor performance, tougher per-tenant backup and restore, and complex auditing if not instrumented.
Tenant‑Dedicated Schemas
Each tenant gets its own schema in the same database instance. Advantages: better logical isolation, easier per-tenant extension or customization, simpler per-tenant backups (schema-level dumps). Limitations: metadata explosion (many schemas), connection management complexity, and limits on simultaneous schema count depending on DB.
Sharding (Per‑Tenant or Range/Hash Shards)
Sharding means splitting tenants across multiple physical database instances. Advantages: strongest isolation, independent scaling and maintenance per shard. Limitations: higher operational cost, routing complexity for queries across shards, and heavier migration work when re-balancing.
Decision framework: pick the right pattern (or combination)
Use a tiered approach for enterprise SaaS:
- Small tenants (low data, low impact): Shared schema + RLS. Lowest cost, fastest feature development.
- Mid-size tenants (moderate volume, occasional spikes): Tenant schemas on shared DB instance. Better control and simpler per-tenant backups.
- Large/high-risk tenants (high volume, regulatory or SLA requirements): Dedicated database/shard. Maximum isolation and performance control.
This hybrid model balances scalability, integration and ROI: keep most tenants on RLS to minimize cost and complexity, while moving heavy or sensitive tenants to schema or shard tiers when justified.
Implementation: step-by-step
The following sequence is a pragmatic path from assessment to production, with concrete implementation notes.
1. Discovery and classification (1–3 weeks)
- Inventory tenants: daily requests, data volume, peak concurrent connections, integrations (BI, ETL), compliance needs.
- Define thresholds for tiering (e.g., >1TB or >10k qps → shard tier).
- Identify reporting and integration contracts that require cross-tenant or per-tenant access.
2. Prototype policies and safety nets (2–4 weeks)
Build an experiment environment to validate RLS policies, schema creation scripts, and a shard routing prototype.
RLS example (Postgres):
-- Enable RLS and use a session setting to enforce tenant_id
ALTER TABLE orders ENABLE ROW LEVEL SECURITY;

-- Application sets tenant id at connection start:
SELECT set_config('app.current_tenant', '42', true);

-- Policy uses current_setting to filter rows
CREATE POLICY tenant_isolation ON orders
  USING (tenant_id::text = current_setting('app.current_tenant'));
Notes: store tenant id as text for robust comparison, validate that application drivers set session variables on each connection or via connection pooler hooks.
3. Schema automation (2–6 weeks)
- Automate schema creation and migrations. Use migration tooling that can apply migrations per schema (Flyway, Liquibase with schema targets).
- Manage schema lifecycle: tagging, versioning, and backward compatibility strategies.
4. Shard routing and metadata (3–8 weeks)
Implement a shard map service: a small metadata table (or service) that maps tenant_id → shard_node. Use consistent hashing or a lookup table for simple maps. The application layer or a routing proxy uses this mapping to direct requests.
Example shard map table:
CREATE TABLE tenant_shard_map (
  tenant_id bigint PRIMARY KEY,
  shard_id text NOT NULL,
  created_at timestamptz DEFAULT now()
);
5. Migration strategies
Choose migration approaches depending on current architecture:
- Lift-and-shift for single large tenants → export/import into new schema/db during a maintenance window.
- Dual‑write followed by shadow read (recommended for low-risk migration). Application writes to both old and new store; reads compare results and switch once stable.
- Online backfill: copy historical data in background, switch traffic when backfill is complete.
6. Cutover, rollback and verification
Always have a rollback plan. For RLS→schema migrations, keep the RLS policy active until you confirm the new schema is correct. For shard migrations, ensure the shard map is versioned and can be rolled back atomically (feature-flagged routing helps).
Performance and scalability considerations
- Indexing: index tenant_id plus frequent query predicates. Use multicolumn and partial indexes where helpful.
- Partitioning: for large tables, use declarative partitioning by tenant_id or time ranges to limit scan costs.
- Connection pooling: per-shard pools and multiplexers (pgbouncer) prevent connection exhaustion when using many schemas or DBs.
- Caching: implement tenant-aware caches (with tenant keys) to reduce DB load on shared instances.
- Throttling: apply per-tenant rate limits to protect overall SLA.
Integration and operational tooling
Enterprise customers often require custom integrations: BI access, backups, and data exports. Decide per tier:
- RLS tier: provide API-based exports and vetted ETL connectors. Expose views for analytics but limit direct DB access.
- Schema tier: offer read-only credentials scoped to the tenant schema; automated schema dumps for backups.
- Shard tier: allow dedicated DB access and integrate with customer-managed network controls (VPC peering, private endpoints).
Security, compliance and data lifecycle
Key controls for enterprise solutions:
- Encryption at rest and in transit across all tiers.
- Audit logging for data access and administrative actions; ensure logs are tenant-tagged.
- Support for data deletion/ERASURE requests—RLS complicates deletion auditing but use per-tenant markers and background sanitization jobs.
- Data residency: for regulated tenants, place their shards/schemas in region-specific clusters.
Monitoring and SLOs
Measure tenant-level and system-level metrics, and set SLAs accordingly:
- Per-tenant request latency (P50, P95, P99).
- DB CPU/memory and cache hit rates per shard.
- Connection counts per shard and pool saturation.
- Storage growth rates per tenant for forecasting and rebalancing.
Use telemetry to trigger automated migrations: for example, when a tenant's storage or CPU usage crosses a defined threshold, plan promotion from RLS→schema or schema→shard.
Cost and ROI considerations
Choices affect both CapEx/Opex and sales/retention economics. Evaluate three cost buckets:
- Infrastructure cost: compute, storage, network across RLS/shared vs dedicated schemas and shards.
- Engineering cost: complexity in code, migrations, and test matrices (multiple schemas increase release-testing effort).
- Revenue/retention impact: enterprise customers may pay premium for dedicated isolation or predictable SLAs.
Simple ROI model:
- Estimate additional monthly infrastructure cost per dedicated DB versus incremental revenue (SLA/dedicated support fees).
- Factor reduced churn/higher ARPU for tenants demanding isolation.
- Include engineering amortized cost of supporting multiple patterns.
Recommendation: aim to keep >70% of tenants in shared RLS tier if performance and compliance allow, and only promote to higher tiers when cost is clearly offset by revenue or risk reduction.
Testing and validation
Before production rollout:
- Load test with tenant-shaped traffic to verify isolation at scale and detect noisy-neighbor scenarios.
- Failure injection: test shard or node failure, simulate connection pool exhaustion, and validate failover logic.
- Security validation: confirm RLS policies, role permissions, and audit trails are effective under different credential scenarios.
Checklist and rollout plan (90-day example)
- Weeks 1–2: Discovery & classification, define tier thresholds.
- Weeks 3–6: Prototype RLS policies, schema automation scripts, and a shard map service.
- Weeks 7–10: Load & integration testing, implement monitoring and per-tenant metrics.
- Weeks 11–12: Pilot migration with a low-risk tenant using dual-write and shadow reads.
- Weeks 13+: Gradual rollout, monitor for performance and cost signals, refine thresholds.
Common pitfalls and how to avoid them
- Assuming RLS is a silver bullet: without indexes and partitioning, RLS can still lead to full-table scans.
- Neglecting connection limits: many schemas or DBs increase connection pressure—plan for pooling.
- Over-optimizing too early: avoid sharding at small scale. Prefer schema-level separation first for moderate tenants.
- Not automating lifecycle: manual schema or shard management becomes unsustainable as tenant count grows.
Final recommendations
For enterprise solutions in 2026, use a pragmatic hybrid model: default to shared schema+RLS for cost efficiency and developer velocity, automate schema separation for mid-size tenants, and provide dedicated shards for large, regulated, or noisy tenants. Instrument per-tenant telemetry, automate tier promotions, and model ROI that includes engineering and operational costs as well as revenue uplift from premium offerings. Integration points—BI access, backups, and security controls—should be defined per tier and automated to reduce friction for enterprise customers.
Implementing multi-tenant data isolation is an exercise in trade-offs. With a clear classification policy, automated tooling and telemetry-driven migrations, engineering teams can deliver scalable, secure, and cost-effective enterprise SaaS platforms that meet customers' integration and compliance needs while maximizing ROI.