Overview
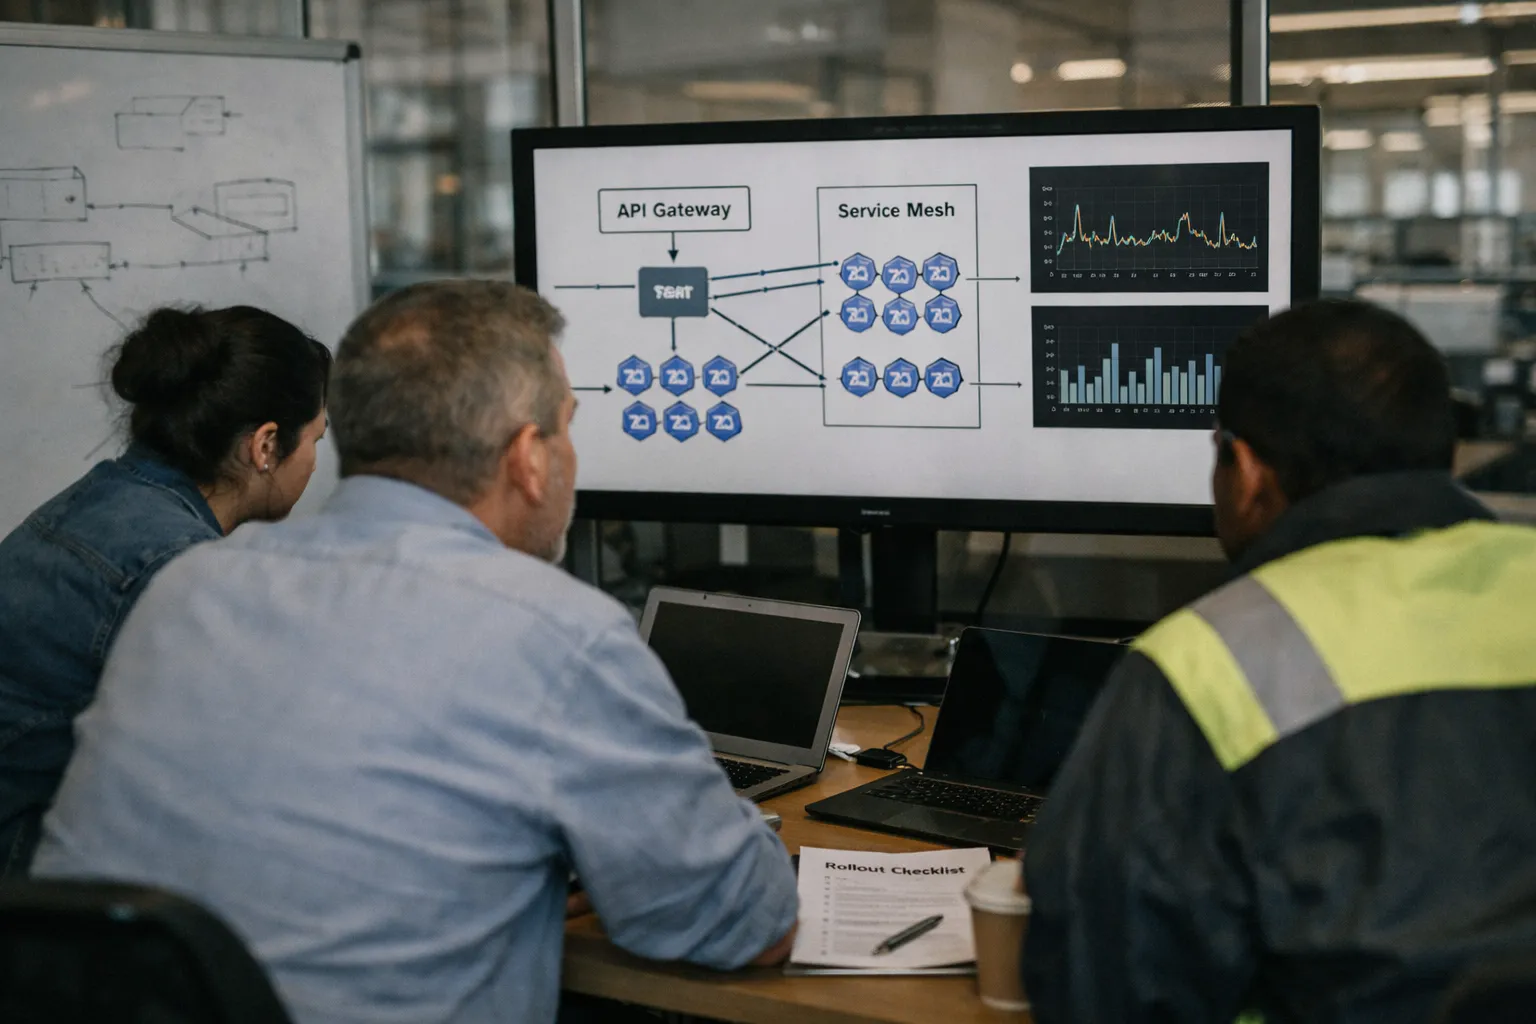
Enterprise platform teams are revisiting the service mesh vs API gateway question again in August 2026. Since May, incremental but meaningful shifts—wider eBPF rollouts, more bundled managed offerings from major cloud vendors, and continued telemetry standardization—have changed the calculus for many organizations. This update focuses on the financial and operational trade-offs you should measure now, with practical pilots and updated time-and-effort estimates so you can decide based on ROI, not vendor marketing.
Background: what shifted since mid‑2026
The last quarter of changes has been evolutionary rather than revolutionary, but a few trends matter for ROI:
- eBPF and sidecarless tech matured in production: Multiple production pilots and early adopters report more stable host-level datapaths and tooling, narrowing the performance and cost gap between sidecar and sidecarless meshes—especially for dense, high-cardinality workloads.
- Managed bundles deepened: Cloud and API-management vendors increasingly sell integrated gateway+mesh packages with joint billing, reducing initial integration work but increasing the need to evaluate lock‑in and SLAs.
- Telemetry consolidation became realistic: OpenTelemetry is now the default choice in nearly every stack we examined; teams that treat telemetry unification as a project upfront avoid duplicate storage and analytics costs later.
- Security and compliance tightened: More organizations now demand automated certificate lifecycle management and SPIFFE-compatible identity as baseline controls—driving early PKI work into any mesh plan.
Data and evidence: what to measure before you decide
The same categories matter—traffic profile, service count, resource delta and operational labor—but refine your pilot metrics to capture ongoing cost drivers:
- Traffic composition (north‑south vs east‑west): capture request volumes, fan‑out ratios and percent of calls that are short‑lived vs streaming. For many teams, even a 10–15% increase in east‑west traffic changes the math.
- Service topology and growth rate: number of services today, projected 12‑month growth, and the number of teams that independently deploy or own services (which drives policy complexity).
- Per‑pod and host resource delta: measure p50/p95 CPU and memory across representative pod types for sidecar, sidecarless/eBPF, and gateway proxies under realistic load—capture tail behavior during spikes.
- Operational labor and friction: SRE hours spent on incidents attributable to network/security, time to onboard a new API or service, and time spent reconciling dual policy engines in hybrid setups.
- Telemetry cost and cardinality: estimate ingestion, storage, and query costs before and after adding mesh-level telemetry; high-cardinality tags from per-service tracing can multiply bills.
Across the pilots I reviewed, teams that instrumented these five areas could quantify an expected 6–18 month payback window for mesh investments when east‑west traffic and service count were sufficiently high. If you can’t reproduce these measurements in a 4–8 week shadow pilot, postpone a full roll‑out.
Multiple perspectives: vendors, platform teams, and SREs (August 2026)
- Vendors: Gateway vendors sell developer portals, API monetization and edge security. Mesh vendors prioritize mTLS, granular traffic control and pervasive telemetry. Lately vendors emphasize packaged experiences—“gateway+mesh as a service”—which speeds deployment but requires careful SLA and exit‑strategy review.
- Platform teams: Small platforms still prefer gateway‑first simplicity. Large, highly interconnected platforms increasingly use meshes to manage internal trust and routing. Many teams now design for hybrid from day one: gateway at the edge, mesh inside the cluster, with a single identity and telemetry plane.
- SREs and finance: SREs flag the twin risks of duplicated policies and observability sprawl. Finance teams want pilots that include engineering hours, telemetry cost projections, and vendor fees before approving broader rollouts.
Scalability and cost: updated considerations
Separate control plane and data plane costs, and add two 2026 realities:
- Bundled managed pricing: Managed control planes and gateway+mesh bundles compress implementation time but shift costs into recurring OPEX. Some buyers find this tradeoff acceptable for faster time-to-value; others report long‑term fees that exceed self‑managed infra after 36–48 months.
- Telemetry and query costs: With richer telemetry from meshes, observability bills are now a first‑order cost. Teams that don’t cap or sample wisely can double or triple monitoring costs within months of a mesh rollout.
Updated rules of thumb (August 2026):
- Gateway-first still fits platforms with fewer than ~75 services and predominantly north‑south traffic, especially when developer portals and API monetization matter.
- Mesh-first becomes compelling for platforms above ~150–200 services with dense east‑west patterns, provided you can staff PKI, observability and incident response needs.
- Hybrid is the default enterprise posture: gateways for edge concerns; meshes (sidecar or sidecarless) for internal trust and traffic control. Plan telemetry and identity unification at design time.
Implementation timelines, updated risks and realistic effort
Shortened timelines are real—managed bundles and better tooling have compressed onboarding—but hidden costs remain:
- API Gateway-first: Managed gateway + existing CI/CD: 2–8 weeks to cover external APIs and developer onboarding. Self-hosted still often takes 2–4 months for enterprise feature parity and security integrations.
- Service Mesh-first: Managed, sidecarless meshes can be rolled out namespace‑by‑namespace in 1–4 months if you accept hosted control planes and baseline policy. Self-managed sidecar meshes often still require 4–10 months to cover mTLS rollout, PKI integration and hardened observability.
- Hybrid: Allow an extra 1–4 months for policy reconciliation, PKI unification and telemetry harmonization—even with managed control planes.
Updated engineering-hours guidance (practical):
- Managed bundle, phased rollout: ~600–2,000 engineering hours (pilot → organization-wide).
- Self-managed, sidecar-heavy migration: ~1,200–3,500 hours depending on service count and compliance needs.
Hidden costs to budget for now:
- Telemetry ingestion/storage growth and added analytics licenses.
- Certificate lifecycle automation and potential managed CA fees.
- Host-level maintenance for eBPF/sidecarless models (kernel compatibility, OS patching).
- Policy translation tooling and runbook updates for on-call teams.
Measuring ROI: concrete KPIs and realistic timelines
ROI models must be tied to measurable outcomes and realistic review points:
- Track developer lead time for API and service changes, and mean time to rollback; target a measurable improvement (for example, a 20% reduction) within 6 months if developer productivity is a goal.
- Measure incident MTTD and MTTR specifically for network/security incidents attributable to service-to-service interactions; set a baseline before enabling mesh-level features like retries and circuit breakers.
- Quantify infrastructure delta (CPU/memory/egress) at p95 traffic and project monthly telemetry spend with and without the mesh.
- Track compliance readiness and time‑to‑audit for regulated workloads as a security ROI measure.
Most teams can expect a 6–18 month window to realize operational ROI if the pilot shows improvements in developer velocity or incident metrics. If a pilot does not show measurable improvement within two quarters, re-assess scope or consider gateway-first for longer.
Updated architectural patterns and best practices
- Start with identity and telemetry: Unify PKI (SPIFFE/SPIRE or centralized CA) and OpenTelemetry schema before installing both gateway and mesh. This one step avoids dual-CA and duplicate telemetry anti-patterns.
- Shadow traffic is mandatory: Require a 4–8 week shadow pilot that mirrors p95 loads and captures CPU/memory delta, tail latency and SRE time to resolve incidents.
- Limit telemetry cardinality: Define sampling and tagging policies up front to control observability bills—reconcile telemetry at the collector, not at the storage layer.
- Plan for rollback and incremental adoption: Roll out mesh features namespace-by-namespace, and keep edge routing on the gateway until internal policies stabilize.
Implications for platform leaders and CIOs
Treat the gateway/mesh decision as a program with measurable checkpoints, not a one‑line procurement. Practical steps:
- Map your service graph and projected growth before vendor talks.
- Run a 4–8 week shadow pilot that measures p50/p95 latency, resource delta and SRE labor impact under representative load.
- Cost implementation as engineering time + recurring managed fees + observability growth; require vendors to validate with shadow traffic.
- Set concrete ROI targets (developer velocity, incident reduction, compliance readiness) and review at 3, 6 and 12 months.
Outlook: what to watch through the rest of 2026
Three levers will meaningfully change the decision landscape:
- Further maturation of eBPF/sidecarless approaches and host observability—if these approaches prove reliably low‑overhead across diverse enterprise workloads, mesh TCO will fall further.
- More bundled gateway+mesh offerings from cloud vendors—these shorten time-to-value but raise vendor-lock and long‑term cost questions.
- Standards work on cross-plane policy translation and telemetry semantics—wider adoption will reduce hybrid complexity if it becomes interoperable across vendors.
Practical next step: map your service graph and run a 4–8 week shadow pilot that captures p95 latency, CPU/memory delta, telemetry cost impact and SRE incident time. That single pilot will give you the measurable inputs needed to choose gateway-first, mesh-first or hybrid based on ROI for your organization.
Do I need both a gateway and a mesh?
Not always. For small platforms with limited east‑west traffic, a managed API gateway often provides the best ROI. For larger, highly connected estates, a mesh adds value. Most enterprises adopt a hybrid approach—gateways at the edge, meshes internally—but make that choice after a representative pilot and by mapping traffic and security needs.
Do managed meshes eliminate operational overhead?
No. Managed control planes reduce time spent on upgrades and some operational burdens, but they don’t remove the need to integrate PKI, telemetry and policies with your systems. Expect some engineering hours to remain and recurring fees to appear; include both in ROI models.
Will eBPF/sidecarless approaches make sidecar meshes obsolete?
No. eBPF reduces per‑pod overhead and can deliver higher density in many workloads, but it introduces host‑level complexity and different failure modes. Expect coexistence: sidecars where isolation and service‑level controls are critical, eBPF where density and latency are the priority. Validate with pilots.
How should I validate vendor claims about performance and cost?
Require shadow‑traffic pilots or A/B tests in staging that mirror production load. Measure p50/p95 latency, CPU/memory delta, telemetry ingestion and incident-handling time. Treat vendor benchmarks as directional—your workload will determine the real numbers.
What short checklist should I follow before approving a rollout?
Map service graph, choose representative workloads for pilot, set KPI targets (developer lead time, MTTD/MTTR, infra delta), run a 4–8 week shadow pilot, then review cost and operational impact at 3 months before broader deployment.